MongoDB Aggregation Pipeline Tutorial: $match, $group, and $lookup
Build MongoDB aggregation pipelines with $match, $group, $unwind, $lookup, $facet and $merge, with worked reports and performance rules.

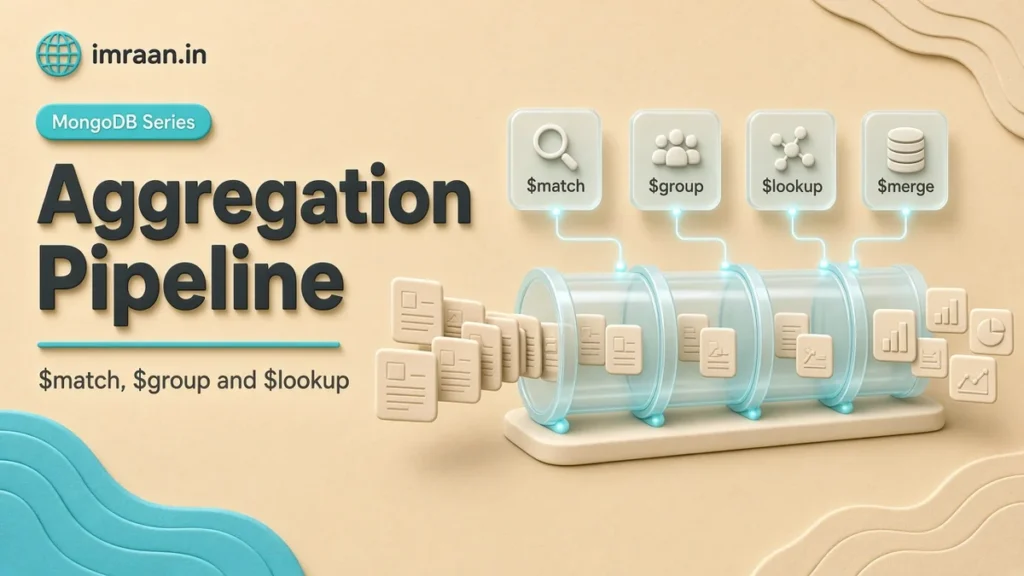
The MongoDB aggregation pipeline is the tool I reach for whenever a question starts with “how many”, “how much” or “which ones, grouped by”. I have replaced plenty of application loops that pulled thousands of documents into memory just to add them up. The pipeline versions were shorter, faster and easier to review. Here I write about how the pipeline works, the stages I use every week, and the rules that keep it from becoming a performance problem.
Every example below runs in the mongo shell on MongoDB 4.2, and every output shown is what that pipeline returns on the sample data. Totals are whole rupees to keep outputs readable; for real money use Decimal128 as in the CRUD tutorial.
The MongoDB Aggregation Pipeline Model
A pipeline is an array of stages. Documents flow from the collection into the first stage, and each stage transforms the stream. The output of one stage becomes the input of the next. Order matters. Filtering and then grouping is not the same as grouping and then filtering, either in result or in cost.
Here is the sample data. If you want to load a larger dataset from a JSON file, I covered that in insertMany in MongoDB via file.
use shop

db.customers.insertMany([
  { _id: "c1", name: "Asha", city: "Pune" },
  { _id: "c2", name: "Vikram", city: "Mumbai" },
  { _id: "c3", name: "Neha", city: "Bengaluru" }
])

db.orders.insertMany([
  { _id: 1, customerId: "c1", status: "paid",      createdAt: ISODate("2019-09-05"), total: 2297, items: [ { sku: "BK-101", qty: 2, price: 499 }, { sku: "HD-200", qty: 1, price: 1299 } ] },
  { _id: 2, customerId: "c2", status: "paid",      createdAt: ISODate("2019-09-18"), total: 499,  items: [ { sku: "BK-101", qty: 1, price: 499 } ] },
  { _id: 3, customerId: "c1", status: "shipped",   createdAt: ISODate("2019-10-02"), total: 799,  items: [ { sku: "MS-310", qty: 1, price: 799 } ] },
  { _id: 4, customerId: "c3", status: "paid",      createdAt: ISODate("2019-10-14"), total: 3397, items: [ { sku: "HD-200", qty: 2, price: 1299 }, { sku: "MS-310", qty: 1, price: 799 } ] },
  { _id: 5, customerId: "c2", status: "cancelled", createdAt: ISODate("2019-10-20"), total: 1497, items: [ { sku: "BK-101", qty: 3, price: 499 } ] },
  { _id: 6, customerId: "c3", status: "paid",      createdAt: ISODate("2019-11-03"), total: 499,  items: [ { sku: "BK-101", qty: 1, price: 499 } ] },
  { _id: 7, customerId: "c1", status: "shipped",   createdAt: ISODate("2019-11-15"), total: 1299, items: [ { sku: "HD-200", qty: 1, price: 1299 } ] },
  { _id: 8, customerId: "c2", status: "paid",      createdAt: ISODate("2019-11-28"), total: 1598, items: [ { sku: "MS-310", qty: 2, price: 799 } ] }
])
A minimal pipeline that ranks customers by revenue from completed orders:
db.orders.aggregate([
  { $match: { status: { $in: ["paid", "shipped"] } } },
  { $group: { _id: "$customerId", orders: { $sum: 1 }, revenue: { $sum: "$total" } } },
  { $sort: { revenue: -1 } }
])
{ "_id" : "c1", "orders" : 3, "revenue" : 4395 }
{ "_id" : "c3", "orders" : 2, "revenue" : 3896 }
{ "_id" : "c2", "orders" : 2, "revenue" : 2097 }
When should you use aggregate instead of find? If you only filter, sort and project whole documents, find is simpler. As soon as you need grouping, computed fields, joins or reshaped output, use a pipeline.
I find it helps to read a pipeline the way you would read a shell command chained with pipes. Each stage should do one job. You should also be able to comment out everything after any stage and look at the intermediate result. When I debug a pipeline that returns the wrong numbers, that is exactly what I do. I run it one stage at a time until the output stops matching what I expect. Pipelines are also plain arrays. So in application code I build them from small functions that return stages. That keeps reports readable and lets me unit test the pieces.
Put $match First
$match filters documents using the same query language as find. At the start of a pipeline it can use indexes, so it decides how much data the rest of the pipeline touches. A $match placed after $group or $project works on computed documents and cannot use a collection index. The optimiser moves some stages around for you, but I write pipelines as if it did not.
db.orders.aggregate([
  { $match: {
      status: { $in: ["paid", "shipped"] },
      createdAt: { $gte: ISODate("2019-09-01"), $lt: ISODate("2019-12-01") }
  } },
  { $count: "completedOrders" }
])
{ "completedOrders" : 7 }
Shaping With $project and $addFields
$addFields (alias $set) adds computed fields and keeps everything else. $project keeps only what you list. I use $addFields for intermediate values and $project near the end to shape the output.
db.orders.aggregate([
  { $match: { status: { $in: ["paid", "shipped"] } } },
  { $addFields: {
      month: { $dateToString: { format: "%Y-%m", date: "$createdAt" } },
      size: { $cond: [ { $gte: ["$total", 1500] }, "large", "small" ] }
  } },
  { $project: { _id: 1, month: 1, size: 1, total: 1 } },
  { $limit: 3 }
])
{ "_id" : 1, "total" : 2297, "month" : "2019-09", "size" : "large" }
{ "_id" : 2, "total" : 499, "month" : "2019-09", "size" : "small" }
{ "_id" : 3, "total" : 799, "month" : "2019-10", "size" : "small" }
Expressions inside these stages are a language of their own. They include arithmetic like $multiply and $round, conditionals like $cond and $switch, string functions, date functions and array operators such as $filter, $map and $reduce. Field paths start with $, and literal strings that happen to start with $ need $literal. That last rule catches people who store currency symbols.
$dateToString uses UTC unless you pass a timezone, such as "Asia/Kolkata". Reports that bucket by day in the wrong zone are a quiet source of wrong numbers.
$group and Accumulators in the Aggregation Pipeline
$group collapses documents that share a key into one output document. The _id is the grouping key, which can be a field, an expression or an object of several fields. Accumulators compute values per group: $sum, $avg, $min, $max, $push for an array of values, and $addToSet for distinct values. $first and $last depend on input order, so put a $sort before them.
Monthly revenue:
db.orders.aggregate([
  { $match: { status: { $in: ["paid", "shipped"] } } },
  { $group: {
      _id: { $dateToString: { format: "%Y-%m", date: "$createdAt" } },
      orders: { $sum: 1 },
      revenue: { $sum: "$total" },
      avgOrder: { $avg: "$total" },
      biggest: { $max: "$total" },
      customers: { $addToSet: "$customerId" }
  } },
  { $addFields: { customers: { $size: "$customers" }, avgOrder: { $round: ["$avgOrder", 0] } } },
  { $sort: { _id: 1 } }
])
{ "_id" : "2019-09", "orders" : 2, "revenue" : 2796, "avgOrder" : 1398, "biggest" : 2297, "customers" : 2 }
{ "_id" : "2019-10", "orders" : 2, "revenue" : 4196, "avgOrder" : 2098, "biggest" : 3397, "customers" : 2 }
{ "_id" : "2019-11", "orders" : 3, "revenue" : 3396, "avgOrder" : 1132, "biggest" : 1598, "customers" : 3 }
The $group reference lists every accumulator. Grouping by several fields is just an object key, such as _id: { customer: "$customerId", month: { $month: "$createdAt" } }, and a null key groups the whole input into one document, which is how I compute grand totals.
Be careful with $push and $addToSet on big groups. The resulting document still has to fit in 16 MiB. So I collect counts or capped samples, never every order id for a popular product.
Latest order per customer with $sort and $first
A question I get asked constantly is “show me each customer’s most recent order”. In 4.2 the pattern is a $sort followed by $group with $first, and the sort has to come first because $first simply takes whichever document reaches the group first:
db.orders.aggregate([
  { $match: { status: { $in: ["paid", "shipped"] } } },
  { $sort: { createdAt: -1 } },
  { $group: {
      _id: "$customerId",
      lastOrder: { $first: "$_id" },
      lastTotal: { $first: "$total" },
      lastAt: { $first: "$createdAt" }
  } },
  { $sort: { _id: 1 } }
])
{ "_id" : "c1", "lastOrder" : 7, "lastTotal" : 1299, "lastAt" : ISODate("2019-11-15T00:00:00Z") }
{ "_id" : "c2", "lastOrder" : 8, "lastTotal" : 1598, "lastAt" : ISODate("2019-11-28T00:00:00Z") }
{ "_id" : "c3", "lastOrder" : 6, "lastTotal" : 499, "lastAt" : ISODate("2019-11-03T00:00:00Z") }
On a large collection, a supporting index lets that $sort read in order instead of sorting in memory. Then explain shows which one you got. For “top three per customer”, replace $first with $push and add a $slice in a following $addFields, keeping in mind that the pushed array is built in full before it gets sliced. What the pipeline in 4.2 does not do well is running totals and moving averages across neighbouring documents. That is because there are no window functions. I compute those in application code from a sorted cursor, which is a short loop and easy to test.
$unwind for Item-Level Analysis
$unwind turns one document with an array into one document per element. That is how you analyse line items:
db.orders.aggregate([
  { $match: { status: { $in: ["paid", "shipped"] } } },
  { $unwind: "$items" },
  { $group: {
      _id: "$items.sku",
      units: { $sum: "$items.qty" },
      revenue: { $sum: { $multiply: ["$items.qty", "$items.price"] } }
  } },
  { $sort: { revenue: -1 } }
])
{ "_id" : "HD-200", "units" : 4, "revenue" : 5196 }
{ "_id" : "MS-310", "units" : 4, "revenue" : 3196 }
{ "_id" : "BK-101", "units" : 4, "revenue" : 1996 }
By default $unwind drops documents whose array is empty or missing. Pass { path: "$items", preserveNullAndEmptyArrays: true } if those should survive. Unwinding multiplies the stream, so an array of 500 elements becomes 500 documents. If you only need a per-document figure, array operators like $sum over "$items.qty" or $reduce inside $addFields avoid the unwind entirely.
$lookup for Joins in a MongoDB Aggregation Pipeline
$lookup performs a left outer join to another collection in the same database. The basic form matches a local field to a foreign field:
db.orders.aggregate([
  { $match: { _id: { $in: [1, 4] } } },
  { $lookup: { from: "customers", localField: "customerId", foreignField: "_id", as: "customer" } },
  { $unwind: "$customer" },
  { $project: { _id: 1, total: 1, name: "$customer.name", city: "$customer.city" } }
])
{ "_id" : 1, "total" : 2297, "name" : "Asha", "city" : "Pune" }
{ "_id" : 4, "total" : 3397, "name" : "Neha", "city" : "Bengaluru" }
The pipeline form, added in 3.6, runs a sub-pipeline per input document. That is how you get “each customer with their latest two orders”. let exposes fields from the input document as variables, and the sub-pipeline refers to them with $$ inside an $expr:
db.orders.createIndex({ customerId: 1, createdAt: -1 })

db.customers.aggregate([
  { $lookup: {
      from: "orders",
      let: { cid: "$_id" },
      pipeline: [
        { $match: { $expr: { $eq: ["$customerId", "$$cid"] } } },
        { $sort: { createdAt: -1 } }, { $limit: 2 },
        { $project: { _id: 1, total: 1 } }
      ],
      as: "recentOrders"
  } },
  { $project: { name: 1, recentOrders: 1 } }
])
{ "_id" : "c1", "name" : "Asha", "recentOrders" : [ { "_id" : 7, "total" : 1299 }, { "_id" : 3, "total" : 799 } ] }
{ "_id" : "c2", "name" : "Vikram", "recentOrders" : [ { "_id" : 8, "total" : 1598 }, { "_id" : 5, "total" : 1497 } ] }
{ "_id" : "c3", "name" : "Neha", "recentOrders" : [ { "_id" : 6, "total" : 499 }, { "_id" : 4, "total" : 3397 } ] }
The same form handles join conditions that are not a simple equality, such as orders inside a date range stored on the input document. The $lookup reference shows both forms side by side.
Always index the foreign field. Without it, every input document triggers a scan of the other collection. In 4.2 the from collection cannot be sharded. So on a sharded cluster the joined collection has to stay unsharded. That is one more reason to keep joins rare. If you find yourself joining the same collections on every request, revisit the model with the schema design post; an extended reference is often the better answer.
$facet and $bucket for Dashboards
$facet runs several sub-pipelines over the same input in one pass, which suits dashboard widgets:
db.orders.aggregate([
  { $facet: {
      byStatus: [ { $sortByCount: "$status" } ],
      bySize: [ { $bucket: { groupBy: "$total", boundaries: [0, 1000, 2000, 5000], default: "other", output: { count: { $sum: 1 } } } } ]
  } }
])
{ "byStatus" : [ { "_id" : "paid", "count" : 5 }, { "_id" : "shipped", "count" : 2 }, { "_id" : "cancelled", "count" : 1 } ], "bySize" : [ { "_id" : 0, "count" : 3 }, { "_id" : 1000, "count" : 3 }, { "_id" : 2000, "count" : 2 } ] }
The whole $facet output is one document, so it is subject to the 16 MiB limit. Also, sub-pipelines inside $facet cannot use indexes. Put a $match before it to narrow the input.
MongoDB Aggregation Pipeline Output: Materialised Views With $merge
$out replaces a whole collection with the pipeline output. $merge, added in 4.2, writes into an existing collection and lets you decide what happens when a document already exists. That makes incremental refreshes possible:
db.orders.aggregate([
  { $match: { status: { $ne: "cancelled" } } },
  { $group: {
      _id: { $dateToString: { format: "%Y-%m-%d", date: "$createdAt" } },
      orders: { $sum: 1 },
      revenue: { $sum: "$total" }
  } },
  { $merge: { into: "dailySales", on: "_id", whenMatched: "replace", whenNotMatched: "insert" } }
])
db.dailySales.find().sort({ _id: 1 }).limit(3)
{ "_id" : "2019-09-05", "orders" : 1, "revenue" : 2297 }
{ "_id" : "2019-09-18", "orders" : 1, "revenue" : 499 }
{ "_id" : "2019-10-02", "orders" : 1, "revenue" : 799 }
In production I schedule this from a job runner and restrict the $match to recent days. That way each run rewrites only the last few days of summaries instead of recomputing history. Dashboards then read the small dailySales collection directly. The $merge reference describes the other whenMatched options, including merge for updating a few fields and a custom pipeline for adding to existing counters. Note that the field you merge on needs a unique index in the target collection; _id always has one, which is why I use it.
Aggregation Pipeline Performance and Limits
Each blocking stage such as $group or $sort has a 100 MB memory limit. Go past it and the pipeline fails with an “Exceeded memory limit” error unless you pass { allowDiskUse: true } as an option to aggregate, which lets those stages spill to temporary files under the data directory. I pass it on reporting pipelines that I know are large. However, I treat the need for it as a signal to filter earlier or add an index, because spilling is much slower. Results come back through a cursor, so the total result can be any size. However, each output document must stay under 16 MiB. The aggregation pipeline limits page has the details.
To see whether a pipeline uses an index, run explain on it, for example db.orders.explain("executionStats").aggregate([...]). On the sample data, a pipeline starting with $match: { customerId: "c1" } and $sort: { createdAt: -1 } shows an IXSCAN on customerId_1_createdAt_-1 with no separate sort stage. The indexing tutorial explains how to design that index, and the aggregation optimisation page lists the reordering the server does automatically.
Decision Framework: Aggregate in the Database or the App?
I aggregate in the database when the input is large and the output is small. Shipping thousands of documents to count them wastes network and memory. I compute in the app when the logic needs data the database does not have, or when results are small and already loaded. For reports that run often over data that changes slowly, I materialise with $merge instead of recomputing on every page view. For live numbers, I run the pipeline on demand with a selective $match and a supporting index.
Where the pipeline runs matters too. Heavy reporting pipelines compete with your application for cache and CPU on the primary. If the report can tolerate data that is a few seconds old, I send it to a secondary with a read preference of secondaryPreferred, or on Atlas to a dedicated analytics node. That way a month-end report never slows down checkout.
Common Aggregation Pipeline Mistakes
The mistake I have seen most is $lookup before $match: joining every order to its customer and only then filtering for one month. Filter first, then join the survivors. Another is $unwind followed by $group on _id just to rebuild the same document with a computed field. Array expressions do that without multiplying the stream. A third is ignoring a large $sort without a supporting index. It works on test data and then spills to disk or fails when the collection grows.
Frequently Asked Questions
Is $lookup slow?
Not inherently. With a $match before it and an index on the foreign field, each lookup is an indexed query. It becomes slow when it runs against unfiltered input or an unindexed field.
What is the difference between $out and $merge?
$out replaces the target collection with the full pipeline output each time. $merge inserts, replaces, merges or keeps documents in an existing collection based on a match field, which allows incremental refreshes. Both must be the last stage.
Can a MongoDB aggregation pipeline use indexes?
Yes, for $match and $sort stages at the start of the pipeline, and for the foreign side of $lookup. Once documents have been reshaped by $group, $project or $unwind, later stages work in memory.
How do I paginate aggregation results?
For small offsets, $skip and $limit after a sort work. For deep pages, use range pagination. Sort on an indexed field, remember the last value, and $match on values beyond it in the next request.
Pick one report your application currently computes in code by fetching documents and adding them up. Rewrite it as a MongoDB aggregation pipeline with $match first and check it with explain. Then compare the response time and the amount of data that crosses the network. That one exercise usually changes how a team thinks about where reporting logic belongs.
Last updated on 26 October 2026
Related articles
How to Migrate from SQL to MongoDB: A Practical Playbook
A phased playbook to migrate from SQL to MongoDB: access patterns, document design, ETL, sync, validation, cutover and…
MongoDB Backup and Restore: mongodump, mongorestore, and What to Test
Back up MongoDB with mongodump, snapshots or managed backup, restore with mongorestore and oplog replay, and test restores…
MongoDB with Node.js: Mongoose vs the Native Driver
Mongoose 5 vs the MongoDB Node.js driver 3: schemas, validation, middleware, populate, lean queries, transactions, and how to…