MongoDB Schema Design: Embedding vs Referencing (and When to Choose)
When to embed and when to reference in MongoDB, with cardinality rules, subset, bucket and extended reference patterns, and worked examples.

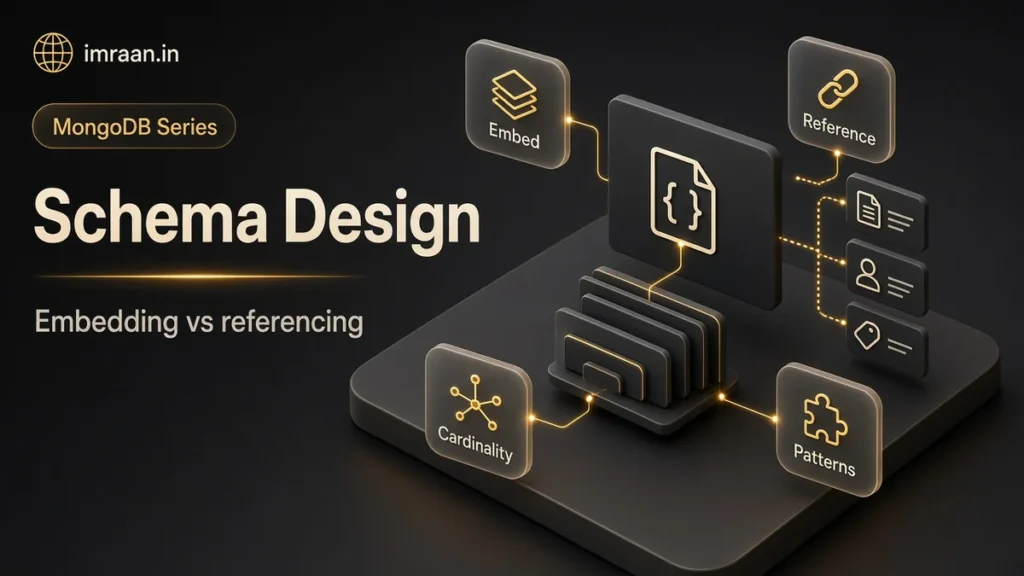
MongoDB schema design is where most projects succeed or fail, and the decision that comes up again and again is whether to embed related data in a document or reference it from another collection. I have reworked enough production models to have strong opinions about it. Here I write about how I make that call, the cardinality rules I use, the patterns I reach for, and the warning signs that a model has gone wrong.
If you are new to documents, read What Is MongoDB? and the CRUD tutorial first, because the update operators matter a lot here.
MongoDB Schema Design Starts From Access Patterns
In relational design you normalise entities first and write queries later. In MongoDB I do it the other way round. Before I create a collection, I list every important read and write, how often it runs, and how fast it has to be. A simple table is enough:
| Operation | Type | Frequency | Latency target | Data needed |
|---|---|---|---|---|
| Show product page | Read | Very high | Under 50 ms | Product, price, top reviews |
| Place order | Write | Medium | Under 200 ms | Customer, items, prices at order time |
| Order history | Read | Medium | Under 100 ms | Orders for one customer, newest first |
| Monthly revenue report | Read | Low | Minutes is fine | All orders in a date range |
The guiding rule follows from that table: data that is used together should be stored together. The product page needs reviews, so some reviews belong near the product. The revenue report runs monthly and can afford an aggregation, so it does not get to shape the main documents.
Embedding in MongoDB Schema Design
Embedding means putting related data inside the parent document as a subdocument or array:
use shop

db.users.insertOne({
  _id: "u1",
  name: "Asha Rao",
  addresses: [
    { label: "home", city: "Pune", postcode: "411001", default: true },
    { label: "work", city: "Pune", postcode: "411014" }
  ]
})
I embed when the relationship is one to one or one to few, when the child data is read with the parent nearly every time, and when it has no life of its own. Addresses fit all three. The benefits are real: one read returns everything, and a write to the user and their addresses is a single atomic operation with no transaction.
Embedding has costs. Any data copied into several documents must be updated in several places. Documents have a 16 MiB limit. And documents that grow constantly get more expensive to update and replicate, long before they reach that limit.
Referencing in MongoDB Schema Design
Referencing means storing the related document’s _id and fetching it separately. I reference when the child set is large or unbounded, when the child has its own lifecycle, or when it is shared by many parents:
db.products.insertMany([
  { _id: "BK-101", name: "Designing Data Systems", price: NumberDecimal("499.00") },
  { _id: "HD-200", name: "USB-C hub", price: NumberDecimal("1299.00") }
])

db.orders.insertOne({
  _id: 5001,
  customerId: "u1",
  createdAt: new Date(),
  items: [ { productId: "BK-101", qty: 1 }, { productId: "HD-200", qty: 1 } ]
})
There are two directions for a reference. A child-to-parent reference stores the parent’s id on each child, like customerId on every order. A parent-to-child reference stores an array of child ids on the parent. Child-to-parent scales to any number of children. An array of ids only works when the array stays small.
To read referenced data you either run two queries from the application or use $lookup in an aggregation. Two simple indexed queries are often faster and easier to cache than one $lookup, so I do not treat $lookup as the default.
Relationship Cardinality Guide
This is the rule set I give teams. It is a starting point, and the access pattern table always wins when the two disagree.
| Relationship | Example | My default |
|---|---|---|
| One to few | User and addresses | Embed |
| One to many | Product and reviews | Embed a subset, reference the rest |
| One to squillions | Device and sensor readings | Reference from the child, or bucket |
| Many to many | Students and courses | Array of ids on the side with fewer links |
“Squillions” is the informal word MongoDB engineers use for relationships where the child count has no practical ceiling. If you cannot say how big the array will get, assume it is in that category.
Patterns That Solve Real Problems
MongoDB documents a set of schema design patterns. These five are the ones I use most.
Subset pattern. Keep the most used part of a large relationship in the parent and the rest in another collection. A product embeds its ten most recent reviews for the product page, while the full review history lives in a reviews collection that the “see all reviews” page queries.
Extended reference pattern. Copy the few fields you always need along with the reference. For orders this is not optional: the order must record the name and price at the time of purchase, not whatever the product says today.
db.orders.updateOne(
  { _id: 5001 },
  { $set: { items: [
    { productId: "BK-101", name: "Designing Data Systems", unitPrice: NumberDecimal("499.00"), qty: 1 },
    { productId: "HD-200", name: "USB-C hub", unitPrice: NumberDecimal("1299.00"), qty: 1 }
  ] } }
)
Bucket, Computed and Outlier Patterns in Schema Design
Bucket pattern. Group many small time-ordered records into one document per time window. Instead of one document per sensor reading, store one document per sensor per hour:
db.readings.updateOne(
  { sensorId: "s-17", hour: ISODate("2019-11-25T10:00:00Z"), count: { $lt: 3600 } },
  {
    $push: { samples: { t: ISODate("2019-11-25T10:15:02Z"), temp: 21.4 } },
    $inc: { count: 1, sumTemp: 21.4 }
  },
  { upsert: true }
)
The count condition caps each bucket. When the bucket is full, the filter stops matching and the upsert starts a new document for the same hour. The precomputed count and sumTemp mean an hourly average is a division on one document rather than an aggregation over 3,600. MongoDB has no special collection type for metrics, so this is how I store sensor and monitoring data, and it cuts both the document count and the index size compared with one document per reading. The manual’s bucket pattern page shows the same idea with stock trades.
Computed pattern. Store results you would otherwise compute on every read. If a product page shows the average rating, keep ratingCount and ratingSum on the product and update them with $inc when a review arrives.
Outlier pattern. Design for the normal case and handle the rare huge one separately. Most books have a few hundred buyers, but a bestseller may have millions. Keep the normal embedded list, and when it passes a threshold set hasOverflow: true and move the extra entries into overflow documents. The application checks the flag only when it needs the full list.
Handling Duplicated Data in Your Schema Design
The extended reference and computed patterns duplicate data, so you need a plan for keeping copies in line. My first question is always: which copies are allowed to be stale? The product name on a historical order should never change. The author name shown on a blog post can lag by a few seconds without anyone caring.
For copies that should follow the source, there are two options. The simple one is an updateMany when the source changes:
db.posts.updateMany({ "author.id": "a1" }, { $set: { "author.name": "Asha R. Rao" } })
The more decoupled one is a change stream, which lets a separate worker react to changes in the source collection. Change streams need a replica set or sharded cluster:
// Node.js driver 3.x
const stream = db.collection("authors").watch(
  [ { $match: { operationType: "update", "updateDescription.updatedFields.name": { $exists: true } } } ],
  { fullDocument: "updateLookup" }
);

stream.on("change", async (change) => {
  const author = change.fullDocument;
  await db.collection("posts").updateMany(
    { "author.id": author._id },
    { $set: { "author.name": author.name } }
  );
  await db.collection("streamState").updateOne(
    { _id: "author-sync" },
    { $set: { resumeToken: change._id } },
    { upsert: true }
  );
});
The worker saves each change’s _id, which is the resume token, after it finishes the work. On restart it reads the saved token and passes it as resumeAfter (or startAfter, new in 4.2) so it picks up where it left off, as long as the token is still inside the oplog window. The change streams documentation explains resume tokens and the fullDocument options.
Transactions as a Last Resort
Multi-document transactions work on replica sets since 4.0 and on sharded clusters since 4.2, and sometimes they are the right answer, such as moving money between two account documents:
db.accounts.insertMany([ { _id: "A", balance: NumberDecimal("500") }, { _id: "B", balance: NumberDecimal("100") } ])

const session = db.getMongo().startSession()
const accounts = session.getDatabase("shop").accounts
session.startTransaction({ writeConcern: { w: "majority" } })
try {
  accounts.updateOne({ _id: "A", balance: { $gte: NumberDecimal("200") } }, { $inc: { balance: NumberDecimal("-200") } })
  accounts.updateOne({ _id: "B" }, { $inc: { balance: NumberDecimal("200") } })
  session.commitTransaction()
} catch (e) {
  session.abortTransaction()
  throw e
} finally {
  session.endSession()
}
db.accounts.find()
{ "_id" : "A", "balance" : NumberDecimal("300") }
{ "_id" : "B", "balance" : NumberDecimal("300") }
A real transfer would also check that the first update matched a document before moving on. I still treat transactions as a sign to look at the model again. They hold locks and cache resources for their duration, they are aborted if they run past the default 60 second lifetime limit, and they add latency. If a write needs a transaction on every request, the data that changes together probably belongs in one document. The transactions production considerations page is worth reading before you rely on them.
A Worked Example: Blog Platform
Here is how I would model a blog with posts, authors, comments and tags.
Access patterns: the post page is the hot read and needs the post body, author name and avatar, tags, the comment count and the latest comments. The author profile page lists their posts. “Load more comments” pages through older comments. Writing a comment must be quick.
db.blogPosts.insertOne({
  _id: "post-42",
  schemaVersion: 2,
  slug: "mongodb-schema-design",
  title: "Embedding vs referencing",
  author: { id: "a1", name: "Asha Rao", avatar: "/img/a1.webp" },
  tags: ["mongodb", "data-modeling"],
  publishedAt: ISODate("2019-11-25T08:00:00Z"),
  commentCount: 0,
  recentComments: []
})

db.comments.createIndex({ postId: 1, createdAt: -1 })
Authors live in their own collection with an extended reference copied into each post. Tags are a small array of strings, indexed for tag pages. Comments go in a comments collection with a compound index on postId and createdAt, and the post keeps the latest ten using the subset pattern:
const c = { _id: ObjectId(), postId: "post-42", user: "Vikram", text: "Clear explanation.", createdAt: new Date() }
db.comments.insertOne(c)
db.blogPosts.updateOne(
  { _id: "post-42" },
  { $inc: { commentCount: 1 }, $push: { recentComments: { $each: , $position: 0, $slice: 10 } } }
)
The post page is one read. “Load more” queries comments by postId with a range on createdAt, served by the index. A post with ten thousand comments has the same document size as one with ten.
If you are coming from a relational model, my SQL to MongoDB migration playbook applies these same ideas to an existing schema.
The schemaVersion field is cheap insurance. When the model changes, new code writes version 3, readers handle both versions, and a background job upgrades old documents at its own pace. That beats a big-bang migration on a live system.
My Decision Framework: Embed or Reference
For each relationship I ask four questions:
- Is the child read together with the parent most of the time? If yes, lean towards embedding.
- Is the number of children bounded and small? If no, reference.
- Does the child change independently and often? If yes, reference, or embed only a stable subset.
- Does anything need to query or update the child on its own? If yes, give it its own collection.
When Not to Embed
Do not embed anything that grows without limit, such as events, logs, messages or followers. Do not embed data with its own lifecycle, like a comment that can be moderated and reported. And do not embed hot shared data, such as a stock count read by every order, into many documents, because every change then becomes a large fan-out update.
Common Schema Design Mistakes
The mistake I have seen most often is embedding every event in the user document: logins, page views, notifications. It works in development and collapses in production as those documents grow towards the size limit and every update rewrites more data. The opposite mistake is just as common: normalising everything like SQL and then running $lookup on every request. Massive arrays of ids on a parent document are the third, because they grow, they bloat indexes, and they are hard to page through.
Frequently Asked Questions
How many items can I embed in an array?
There is no fixed number, only the 16 MiB document limit. My practical rule is that if you cannot name a small upper bound, think tens rather than thousands, the array should become its own collection or a bucket.
Should I use DBRef?
Usually not. A DBRef is a convention for storing a collection name and id together, but most drivers do not resolve it automatically and $lookup does not use it. A plain field holding the referenced _id is simpler and is what I use.
Can I change from embedding to referencing later?
Yes. Write the new shape alongside the old one, migrate in batches with a script or a pipeline using $merge, and use a schemaVersion field so code can read both during the switch. It is real work, which is why starting from access patterns pays off.
Do I need transactions if I embed?
Not for changes inside one document, because single document writes are atomic. You only need a transaction when one logical change must update several documents and partial success is unacceptable.
Take your largest collection today and check two numbers: the size of its biggest documents (Object.bsonsize(doc) in the mongo shell gives the size of one document in bytes) and the longest arrays inside them. If either is growing month after month, that is the part of your MongoDB schema design to fix first, and the indexing tutorial is the natural next step once the shape is right.
Last updated on 26 October 2026
Related articles
How to Migrate from SQL to MongoDB: A Practical Playbook
A phased playbook to migrate from SQL to MongoDB: access patterns, document design, ETL, sync, validation, cutover and…
MongoDB Backup and Restore: mongodump, mongorestore, and What to Test
Back up MongoDB with mongodump, snapshots or managed backup, restore with mongorestore and oplog replay, and test restores…
MongoDB with Node.js: Mongoose vs the Native Driver
Mongoose 5 vs the MongoDB Node.js driver 3: schemas, validation, middleware, populate, lean queries, transactions, and how to…