How to Read MongoDB explain() Output and Find Slow Queries
Read MongoDB explain() output, compare keys and docs examined, use the profiler and slow query log, and fix slow queries in the right order.

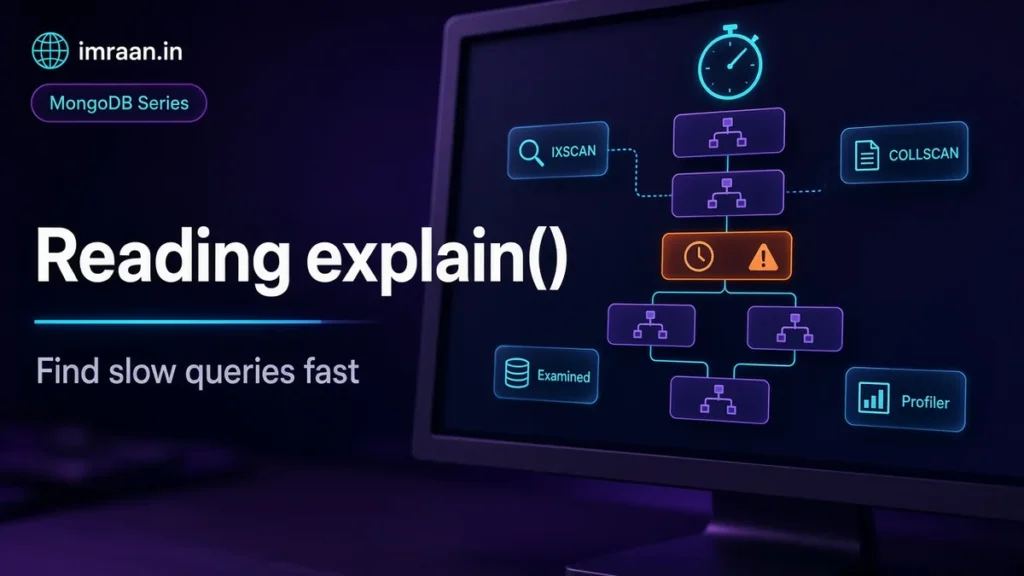
MongoDB explain output looks intimidating the first time you see it. It is a deep JSON tree full of stage names and counters. After years of chasing slow pages, I read it almost entirely through a handful of fields. I find that is enough for most performance problems. Here I write about how I read explain, how I find the queries worth explaining in the first place, and the order in which I try fixes.
Examples use the mongo shell against MongoDB 4.2. The numbers are from a real run on the sample data below. If index design is new to you, read the indexing tutorial first. Nearly every fix here ends in an index, and my broader database indexing guide covers the theory behind that.
use shop

const base = ISODate("2019-10-01T00:00:00Z").getTime()
const statuses = ["pending", "paid", "shipped", "cancelled"]
const docs = []
for (let i = 0; i < 50000; i++) {
  docs.push({ customerId: i % 1000, status: statuses[i % 4], createdAt: new Date(base + i * 60000), total: 100 + (i % 900) })
}
db.orders.insertMany(docs)
db.orders.countDocuments({})
The Three MongoDB explain Verbosity Modes
explain() takes one of three verbosity modes, and the choice matters:
"queryPlanner"(the default) shows the plan the optimiser chose without running the query. It is cheap and safe."executionStats"runs the winning plan to completion and reports what it did: documents returned, keys and documents examined, and time."allPlansExecution"also reports partial statistics for the candidate plans that lost during plan selection.
I use executionStats almost every time, because a plan without execution numbers hides the thing I want to know. You can explain more than find. db.orders.explain("executionStats").aggregate([...]) works for pipelines, as covered in the aggregation pipeline tutorial, and the same explain() helper wraps update, remove, count and distinct. Be careful with writes. Explain with executionStats on an update evaluates the plan but does not apply the change. That makes it a safe way to check that a bulk update will use an index.
db.orders.find({ customerId: 42 }).sort({ createdAt: -1 }).limit(20).explain("executionStats").executionStats.totalDocsExamined
50000
Reading the Winning Plan in MongoDB explain
The queryPlanner.winningPlan field is a tree of stages. Data flows from the innermost stage outwards, so I read it from the bottom up. Here is the winning plan for the query above, trimmed to the useful fields:
{
  "stage" : "SORT",                       <- sort in memory, keep the top 20
  "sortPattern" : { "createdAt" : -1 },
  "limitAmount" : 20,
  "inputStage" : {
    "stage" : "SORT_KEY_GENERATOR",       <- extract the sort key from each document
    "inputStage" : {
      "stage" : "COLLSCAN",               <- read every document in the collection
      "filter" : { "customerId" : { "$eq" : 42 } },
      "direction" : "forward"
    }
  }
}
The stage names you will meet most often:
COLLSCAN: a full collection scan. Fine on tiny collections, a warning everywhere else.IXSCAN: an index scan. CheckindexNameandindexBoundsto see how tight the scan is.FETCH: reading full documents after an index scan. Absent in a covered query.SORT: an in-memory sort, meaning no index provided the order. In 4.2 it sits on top of aSORT_KEY_GENERATORstage.PROJECTION_SIMPLE,PROJECTION_DEFAULTorPROJECTION_COVERED: shaping the output.LIMITandSKIP: what they sound like.
4.2 also gave each query shape a queryHash, which appears in profiler entries and slow query log lines. So you can tie together every run of the same query regardless of the literal values. The explain results reference documents every field. My reading strategy never changes: find the leaf stage, then work outwards.
rejectedPlans lists candidates that lost. When a query has several usable indexes, MongoDB races the candidates for a short trial period, picks the one that produced results most efficiently, and stores that choice in the plan cache for queries with the same shape. Explain itself ignores the cache and always re-plans. That is worth remembering when explain says one thing and production does another.
The Three Numbers That Matter in MongoDB explain
From executionStats, I compare three numbers:
nReturned: documents the query returned.totalKeysExamined: index entries scanned.totalDocsExamined: documents read.
In an ideal plan all three are close to equal. Here is the query before and after the right index:
db.orders.createIndex({ customerId: 1, createdAt: -1 })
const s = db.orders.find({ customerId: 42 }).sort({ createdAt: -1 }).limit(20).explain("executionStats").executionStats
;({ returned: s.nReturned, keys: s.totalKeysExamined, docs: s.totalDocsExamined })
| nReturned | totalKeysExamined | totalDocsExamined | Sort stage | |
|---|---|---|---|---|
| Before index | 20 | 0 | 50,000 | In memory |
| After index | 20 | 20 | 20 | None |
When keys examined is far higher than returned, the index is not selective for this query. Usually that is because a range field sits before an equality field. When documents examined is far higher than returned, the filter is being applied after the fetch. In other words, a field from the filter is missing from the index. A SORT stage on a large result set is the third red flag. It must read every matching document before returning the first one, and in 4.2 a find that needs more than 32 MB for its in-memory sort fails outright rather than spilling to disk.
I treat executionTimeMillis as the least reliable of these numbers. It depends on whether the data was in cache, what else the server was doing, and the hardware. The examined counts are the same on a laptop and in production, which makes them the right thing to compare.
Finding Slow Queries to Feed Into MongoDB explain
Explain answers “why is this query slow”. You still need to find which queries are slow. MongoDB gives you three tools.
The slow query log. Every mongod logs operations that take longer than slowms, 100 milliseconds by default. Each slow operation is one plain text line that includes the namespace, the filter, planSummary, keysExamined, docsExamined, queryHash and the duration in milliseconds at the end. grep on COLLSCAN is a crude but surprisingly effective first pass. For anything more, I run mloginfo --queries from the open source mtools package. It groups log lines by query pattern and sorts them by total time.
The database profiler. The profiler writes operation details into the capped system.profile collection of each database. Level 0 is off, level 1 records operations slower than slowms, and level 2 records everything:
db.setProfilingLevel(1, { slowms: 50 })
db.getProfilingStatus().slowms
Then find the worst offenders by grouping on query shape. Profiler entries in 4.2 carry a queryHash, which makes this grouping clean:
db.system.profile.aggregate([
  { $match: { ns: "shop.orders" } },
  { $group: {
      _id: "$queryHash",
      count: { $sum: 1 },
      totalMillis: { $sum: "$millis" },
      docsExamined: { $sum: "$docsExamined" },
      plan: { $first: "$planSummary" },
      example: { $first: "$command.filter" }
  } },
  { $sort: { totalMillis: -1 } },
  { $limit: 5 }
])
I sort by total time rather than maximum time. A 60 ms query that runs ten thousand times an hour matters more than a 2 second report that runs once a day. The profiler documentation covers sampling, which lets you profile a fraction of operations on busy systems.
Running operations. For something slow right now, $currentOp shows what is executing:
db.getSiblingDB("admin").aggregate([
  { $currentOp: { allUsers: true } },
  { $match: { secs_running: { $gte: 5 } } },
  { $project: { opid: 1, secs_running: 1, ns: 1, planSummary: 1 } }
])
db.killOp(opid) stops a runaway operation. I use it sparingly and only once I know what the operation is, since killing a write midway leaves whatever it had already done.
Worked Example: MongoDB explain on a Slow Order History Page
Here is a pattern I have seen many times. Customers complain that their order history page is slow, and it gets worse as the business grows. The query is the one above: one customer’s orders, newest first, twenty per page.
The profiler entry gives it away even before explain. It shows "planSummary" : "COLLSCAN", "docsExamined" : 50000, "nreturned" : 20 and "hasSortStage" : true. Explain confirms a COLLSCAN under a SORT. The query does the same work for every customer regardless of how many orders they have, and that work grows with the collection.
The fix follows the Equality, Sort, Range rule: equality on customerId, then sort on createdAt. After creating { customerId: 1, createdAt: -1 }, the plan becomes LIMIT, FETCH, IXSCAN with bounds customerId: [42, 42], twenty keys and twenty documents examined, and no sort stage. The cost of the page now depends on the page size, not the collection size. That is the property you want on every hot path.
Query Shapes and the Plan Cache
Occasionally the planner picks a worse index, usually because the trial period favoured a plan that was fast for one parameter value and slow for others. First, try clearing the cached plans for the collection so it re-plans:
db.runCommand({ planCacheClear: "orders" })
If the problem keeps coming back, hint() forces an index for one query in code. A hint is a last resort, because it keeps forcing that index after data and indexes change. The server-side alternative is an index filter, which limits the indexes the planner may consider for one query shape without touching application code:
db.runCommand({
  planCacheSetFilter: "orders",
  query: { customerId: 42, status: "paid" },
  sort: { createdAt: -1 },
  indexes: [ { customerId: 1, createdAt: -1 } ]
})

db.orders.find({ customerId: 7, status: "paid" }).sort({ createdAt: -1 }).explain().queryPlanner.indexFilterSet
true
The literal values in the filter only define the shape, so the filter applies to the query for customer 7 as well. indexFilterSet: true in explain is how you confirm it took effect. Index filters live only in memory. They disappear when the mongod restarts, and on a replica set you set them on each member. I keep the commands in a runbook next to the reason they exist, and I treat any filter that has been in place for more than a few weeks as a sign that the index design needs another look. The query plans page explains how the plan cache works and where filters fit in.
Atlas and Tooling
On Atlas, the Performance Advisor and the Real-Time Performance Panel do much of this work for you. The advisor reads the slow query log, groups slow operations by shape and suggests indexes, and the panel shows what is running right now. Treat suggestions as input, not orders. An advisor sees one slow query; you know which indexes already exist and what each one costs on writes. On self-managed clusters, mloginfo from mtools or a small script that groups slow log lines by queryHash gets you most of the way.
Decision Framework: Fix Order
When I find a slow query, I try fixes in this order. First the index, since it is cheap, reversible and usually enough. Then the query shape: a projection that allows covering, a range pagination instead of a deep skip, or a narrower filter. Then the schema, when the query is slow because the data is shaped wrong for it. Hardware comes last. More RAM hides a missing index only until the data grows again.
Common Profiling and explain Mistakes
The mistake I have seen most is leaving the profiler at level 2 in production after a debugging session. It records every operation, adds write load and churns the system.profile collection. Next is trusting executionTimeMillis from a single warm run. That only tells you how fast the query is when everything is already cached. The third is a hint() hard-coded years ago that now forces a worse index than the planner would pick.
Frequently Asked Questions
What does SORT_KEY_GENERATOR mean?
It is the stage that pulls the sort key out of each document so the SORT stage above it can order them. You only see it beneath an in-memory SORT, so it means the same thing as that stage: no index provided the order, and MongoDB sorted the results in memory. A good index removes both stages.
Is a covered query always faster?
Usually, because it skips fetching documents, but not always by much. If the documents are small and already in cache the gain is modest. Also, making an index wider so it can cover a query increases its size and write cost.
Does the profiler slow down the database?
At level 1 with a sensible slowms, the overhead is small because it only records slow operations. Level 2 records everything and does add load. Sampling with sampleRate reduces the cost on busy systems.
Why does MongoDB explain show the wrong index winning?
Plan selection runs a short trial on the first query of a shape and caches the winner. If that first query had unusual parameter values, the cached plan may suit them and not the common case. Clearing the plan cache, improving the index so one candidate clearly wins, or pinning it with an index filter are the fixes, in that order.
Turn on profiling at 100 ms on a staging copy with realistic data, run your main user flows, and group system.profile by query shape. Explain the top three shapes with executionStats, compare examined counts to returned counts, and fix the worst ratio first. The same habit applied before each release catches most slow queries before your users do.
Last updated on 26 October 2026
Related articles
How to Migrate from SQL to MongoDB: A Practical Playbook
A phased playbook to migrate from SQL to MongoDB: access patterns, document design, ETL, sync, validation, cutover and…
MongoDB Backup and Restore: mongodump, mongorestore, and What to Test
Back up MongoDB with mongodump, snapshots or managed backup, restore with mongorestore and oplog replay, and test restores…
MongoDB with Node.js: Mongoose vs the Native Driver
Mongoose 5 vs the MongoDB Node.js driver 3: schemas, validation, middleware, populate, lean queries, transactions, and how to…