How to Deduplicate Data in Adobe Campaign Classic Workflows
How I deduplicate data in Adobe Campaign Classic: the Deduplication activity, union first, choosing the record to keep, and merging duplicates.

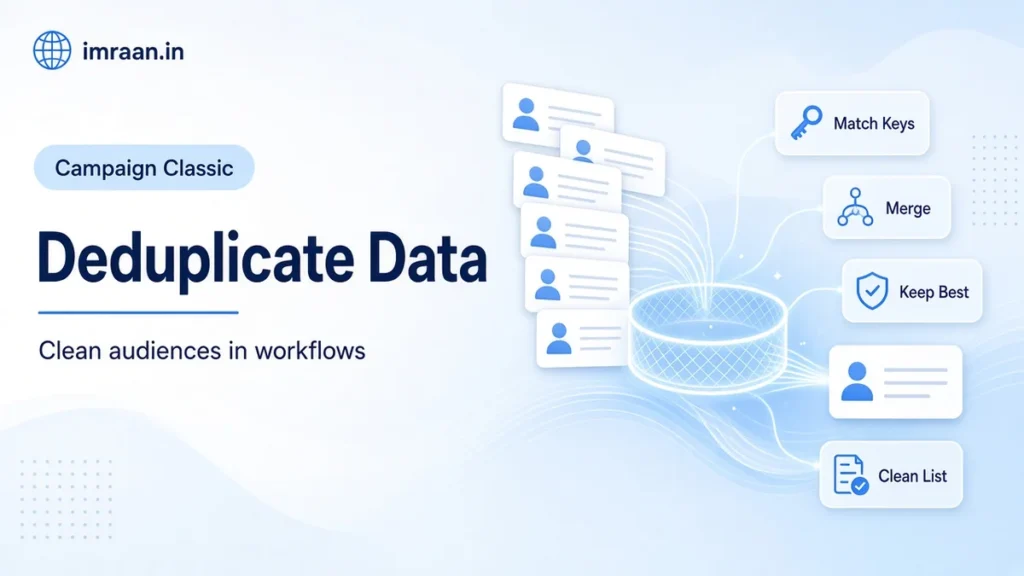
Duplicate profiles are the most common data problem I find when I audit a Campaign Classic instance. They inflate counts, split a person’s history across two records, and can send the same email twice to the same inbox. Knowing how to deduplicate data properly, and where in the flow to do it, saves a lot of awkward conversations with the marketing team.
Here I write about the three places duplicates come from, the Deduplication activity in detail, and the approach I use to clean up a recipient table that already has them. The worked example is a cleanup I would plan for a team that merged two lists.
Where duplicates come from
In my experience duplicates come from three sources, and each needs a different fix.
Incoming files. The same person appears twice in one import file, or in two files loaded on the same day. This is the easiest case, because you can catch it before anything reaches the database.
Delivery targets. A workflow combines several queries, and one recipient matches more than one. Without deduplication, they receive the message twice.
The recipient table. Two records exist for the same person, usually because an import reconciled on email and the person changed address, or because two lists were loaded without a shared key. This is the hardest case, because each record has its own history.
Prevention is much cheaper than cleanup, which is why Adobe’s import best practices insist on deduplicating and reconciling during every import, even when the source team promises the file is clean.
Choosing criteria before you deduplicate data
The criterion is the decision that matters most, and it depends on the data rather than on the activity.
Email works well for delivery targets, because the point is one message per inbox. It is a weak identity key for people, because addresses change and families share them.
Mobile number has the same strengths and weaknesses for SMS. Normalise the format first, or +44 7700 900123 and 07700900123 will not match.
A source system key, such as a CRM ID, is the best criterion when you have it, because it was designed to identify one person. If your data has one, deduplicate on it and use email only as a fallback.
Combinations such as last name plus postcode plus date of birth can work for direct mail lists without email, but test them on a sample first. They tend to catch real duplicates and a few false ones, and the false ones are what people complain about.
Whatever you choose, normalise the fields before comparing. Lower-case email, trimmed spaces and one phone format will catch more duplicates than any clever method choice.
How to deduplicate data with the Deduplication activity
The Deduplication activity removes duplicate rows from its inbound population. You configure it through Edit configuration:
- Targeting dimension. Usually Recipients. If the data comes from a file and is not yet in the database, choose the temporary schema option so the activity works on the work table.
- Criteria. The field or fields whose identical values mark a duplicate. Email is the common choice for delivery targets. For files, use whatever combination you trust to identify a person.
- Method. How to choose which record to keep.
- Number of records to keep. Almost always one.
The main outbound transition carries the records kept. If you enable Generate complement, a second transition carries the duplicates that were removed, which I always switch on. Being able to see what was discarded is what turns a black box into something you can check.
Choosing which record to keep
The method decides which record survives. The options are:
- Choose for me: picks one at random. Fine for a delivery target where the records are identical for practical purposes.
- Following a list of values: you set a priority on a field’s values. For example, keep the record whose source is
CRMbefore one whose source isWebsite. - Non-empty value: keeps records where a given expression is filled, for example the one with a mobile number.
- Using an expression: keeps the record with the highest or lowest value of an expression, such as the most recent modification date.
For delivery targets I use Choose for me, because the goal is simply to send once. For anything that will change the database, I never pick at random. I use an expression or a priority list, so the result is the same every time the workflow runs and someone can explain why a record won.
Deduplicate data after a union, not before
This is the mistake I see most. Deduplication processes each inbound flow separately. If a recipient appears in the result of two queries that both connect to the same Deduplication activity, they are not treated as duplicates of each other.
The fix, which the documentation describes, is to put a Union activity first to combine the flows into one transition, and then deduplicate the union’s output.
Query: newsletter subscribers  \
Query: recent purchasers        -> Union -> Deduplication (email) -> Delivery
Query: app users               /
The Union activity has its own reconciliation option, which can merge records on their ID. That handles the case where the same recipient record appears in two queries. It does not handle two different records with the same email, which is why the Deduplication activity is still needed after it.
Deduplicating a delivery target
For a delivery, the goal is one message per address. Two options work together.
In the workflow, deduplicate on email after the union, with Choose for me, and send the complement to a list if you want a record of who was removed.
In the delivery itself, the target properties include an option to exclude duplicate addresses during delivery. The standard templates I have worked with enable it by default, and I leave it on. It is a safety net at sending time, but I do not rely on it alone, because I want the workflow counts to reflect what will actually be sent.
Deduplicating an incoming file
In an import, deduplicate the new records before inserting them. If the file has two rows for the same new person, both have a recipient ID of 0 after reconciliation, and inserting both creates a duplicate on the first day.
Two settings matter here. Set the targeting dimension to the temporary schema created by the enrichment, and in the advanced parameters disable the automatic filtering of 0 ID records. Without that option, the activity filters out every new row, since they all have an ID of 0. I walk through the whole import in my recipient import guide.
Cleaning duplicates already in the recipient table
When duplicates are already in the database, removing one record is rarely enough. Each record may have subscriptions, delivery logs, tracking logs and list memberships. Deleting a record can delete or orphan that history, depending on link integrity.
The Update data activity has an operation type built for this: Update and merge collections. The Update data documentation explains it. You choose the primary record, select which collections to move from the secondary records to the primary, define rules for which field values win, and choose what happens to the secondary records afterwards, including deleting them once their collections have been moved.
I treat this as a careful, one-off operation rather than something to schedule, and I always run it first on a copy of production.
Worked example: cleaning up after a list merge
Here is a hypothetical brief. A retailer loaded two customer lists into Campaign, one from its web shop and one from its stores, without a shared key. Many customers now exist twice with the same email. They want one record per email, keeping the most recently modified one, with subscriptions moved to the survivor.
Step 1: measure the problem. Before touching anything, I check how many emails are duplicated with a quick script in a JavaScript activity, so I have a baseline:
var query = xtk.queryDef.create(
  <queryDef schema="nms:recipient" operation="select" lineCount="50">
    <select>
      <node expr="@email" alias="@email"/>
      <node expr="count(@id)" alias="@records"/>
    </select>
    <where>
      <condition expr="@email IS NOT NULL"/>
    </where>
    <groupBy>
      <node expr="@email"/>
    </groupBy>
    <having>
      <condition expr="count(@id) >= 2"/>
    </having>
  </queryDef>
);
var res = query.ExecuteQuery();
for each (var r in res.recipient)
  logInfo(r.@email + " has " + r.@records + " records");
The lineCount keeps the test output short. The log gives a sample of affected addresses to check by hand in the console.
Step 2: select the duplicated recipients. A Query activity on Recipients with a condition that the email is in the set of duplicated emails. In the query editor, that is a sub-query with a grouping on email and a count of at least two, the same approach I describe in my query activity guide.
Step 3: decide the survivor. A Deduplication activity on email, method Using an expression, keeping the highest value of the last modified date, with Generate complement enabled. The main transition holds the survivors. The complement holds the records I will merge away.
Reviewing and merging before you deduplicate data
Step 4: review before changing anything. Send both transitions to lists, stop there, and look at a sample of pairs with the marketing team. This is the step people skip and regret. Sometimes two records with the same email really are two people, such as a shared family address.
Step 5: merge. Once the lists are agreed, use Update data with Update and merge collections to move subscriptions from secondary to primary records, apply field rules, and delete the secondary records.
Step 6: stop it happening again. Add a stable key to the recipient table and reconcile both sources on it in future imports.
Mistakes that create or hide duplicates
- Deduplicating before the union. Duplicates across flows survive.
- Random selection for database changes. The survivor changes between runs and nobody can explain it.
- Deleting duplicates without merging. Subscriptions and history disappear with them.
- Not generating the complement. You cannot check what was removed.
- Fixing the table but not the import. The duplicates come back next week.
Frequently asked questions
Can I deduplicate data on more than one field?
Yes. You can choose several criteria, for example email and last name together. Use a combination you trust to identify one person, and test it on real data first.
Does the delivery remove duplicates on its own?
The delivery’s option to exclude duplicate addresses removes repeated addresses at sending time. Deduplicating in the workflow is still worth doing so your counts, lists and control groups are accurate.
Should I delete or archive duplicate recipients?
If you merge collections first, deleting the secondary records is clean. If you are not confident in the merge rules, moving duplicates to an archive folder first is a safer intermediate step.
How often should I deduplicate data?
I run the counting query after every new data source goes live and then periodically. If the count grows, the import needs fixing.
The next post in the series turns to workflow best practices, including how I name, schedule and supervise workflows like these so they keep working after the person who built them moves on.
Last updated on 26 October 2026
Related articles
Adobe Campaign Classic Operator Roles and Permissions: Access Control Explained
Set up Adobe Campaign operator permissions properly: operators, groups, named rights, folder access and a worked team design.
How to Debug Workflow Errors in Adobe Campaign Classic
How I debug Adobe Campaign workflow errors: journals, SQL logging, stuck activities, common messages and a repeatable triage…
How to Integrate Adobe Campaign Classic with External CRMs and Legacy Systems
How to integrate Adobe Campaign Classic with CRMs and legacy systems: CRM connectors, FDA, file exchange and SOAP,…