MongoDB Indexing Tutorial: Types, Creation, and When to Use Each
MongoDB index types explained: compound with the ESR rule, multikey, text, geo, hashed, wildcard, partial and TTL, plus safe builds and usage stats.

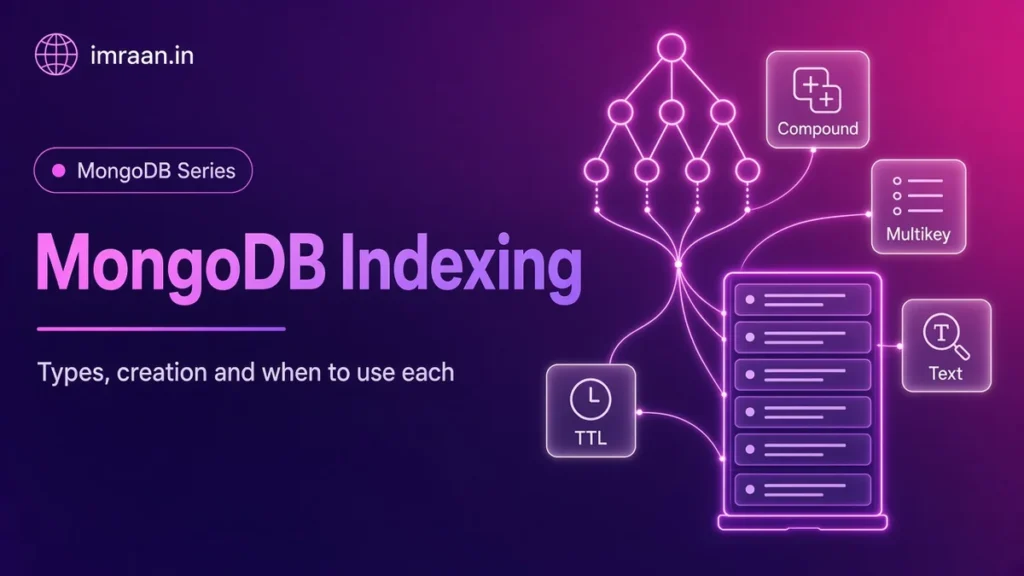
MongoDB indexing is the single biggest performance lever you control as an application developer. Hardware, caching and sharding all help, but none of them rescue a query that has to scan every document. Here I write about the index types MongoDB offers, how I choose between them, how to build them without hurting production, and how to measure which ones are earning their keep. If you want the general theory first, my post on database indexing covers it independent of any database.
The examples run in the mongo shell against MongoDB 4.2, and the outputs below come from a 4.2 replica set. They build on the query syntax from the CRUD tutorial.
How MongoDB Indexing Works
A MongoDB index is a B-tree of field values pointing to documents. Without a suitable index the query planner falls back to a collection scan, shown as COLLSCAN in explain output. It then reads every document. With one it walks the tree, shown as IXSCAN, and fetches only the matching documents. If every field the query filters on and returns is in the index, MongoDB can answer from the index alone. That is a covered query and it skips the document fetch entirely.
Indexes are not free. Every insert, every delete, and every update that touches an indexed field must also update each affected index. Indexes also compete for memory. The WiredTiger cache holds the hot parts of both data and indexes, and the set of indexes and documents your workload touches regularly (the working set) should fit in RAM. An index that is never used still costs writes and memory.
Let me build a sample collection so the numbers below are real:
use shop

const base = ISODate("2019-11-01T00:00:00Z").getTime()
const statuses = ["pending", "paid", "shipped", "cancelled"]
const docs = []
for (let i = 0; i < 20000; i++) {
  docs.push({
    customerId: i % 500,
    status: statuses[i % 4],
    createdAt: new Date(base + i * 60000),
    total: NumberDecimal(String(100 + (i % 900))),
    items: [ { sku: "SKU-" + (i % 50), qty: 1 + (i % 3) } ]
  })
}
db.orders.insertMany(docs)
db.orders.countDocuments({})
20000
And a small helper that pulls the interesting numbers out of explain:
function summary(cursor) {
  const e = cursor.explain("executionStats")
  const s = e.executionStats
  return { returned: s.nReturned, keysExamined: s.totalKeysExamined, docsExamined: s.totalDocsExamined }
}

summary(db.orders.find({ status: "paid" }).sort({ createdAt: -1 }).limit(20))
{ "returned" : 20, "keysExamined" : 0, "docsExamined" : 20000 }
Twenty results, twenty thousand documents read, plus an in-memory sort. That ratio is what I look for first. I go much deeper into reading plans in the post on explain and slow queries.
Single Field and Compound Indexes
A single field index on status would narrow the search but still leave a sort. The right index for “latest orders with a given status” is compound:
db.orders.createIndex({ status: 1, createdAt: -1 })
summary(db.orders.find({ status: "paid" }).sort({ createdAt: -1 }).limit(20))
{ "returned" : 20, "keysExamined" : 20, "docsExamined" : 20 }
Twenty keys, twenty documents, no sort stage. The index returns entries already in the right order and the planner stops after the limit.
Field order in a compound index matters because of the prefix rule. An index on { status: 1, createdAt: -1 } can serve queries on status alone, or on status plus createdAt. It cannot efficiently serve a query on createdAt alone:
summary(db.orders.find({ createdAt: { $gte: ISODate("2019-11-10") } }).sort({ createdAt: -1 }).limit(20))
{ "returned" : 20, "keysExamined" : 0, "docsExamined" : 20000 }
Back to a collection scan. If that query matters, it needs its own index starting with createdAt.
The same index can also cover a query. If the projection asks only for fields stored in the index and excludes _id, MongoDB never touches the documents:
summary(db.orders.find({ status: "paid" }, { _id: 0, status: 1, createdAt: 1 }).sort({ createdAt: -1 }).limit(20))
{ "returned" : 20, "keysExamined" : 20, "docsExamined" : 0 }
Zero documents examined. In the plan this shows as PROJECTION_COVERED over the IXSCAN, with no FETCH stage. Covered queries are worth designing for on hot read paths such as list pages and lookups that return a handful of fields.
The ESR rule for compound index order
For compound indexes I follow the Equality, Sort, Range rule: fields matched by equality go first, then the sort fields, then fields filtered by a range. For “paid orders for customer 42 over 500, newest first” that gives:
db.orders.createIndex({ customerId: 1, status: 1, createdAt: -1, total: 1 })
Equality fields first means the index narrows to a tight slice. Sort fields next means that slice is already ordered. Range fields last means the range filter happens while walking an ordered slice instead of breaking the order. Put the range before the sort and MongoDB has to sort in memory again.
Sort direction only matters when you sort on more than one field. A single field index can be walked in either direction. However, { a: 1, b: -1 } supports sort({ a: 1, b: -1 }) and its exact reverse, not sort({ a: 1, b: 1 }).
Multikey Indexes
Index a field that holds an array and MongoDB creates a multikey index automatically, with one index entry per array element:
db.orders.createIndex({ "items.sku": 1 })
db.orders.countDocuments({ "items.sku": "SKU-7" })
400
The main restriction is simple. In a compound multikey index, at most one of the indexed fields can be an array in any single document. MongoDB refuses to insert a document that breaks this rule for an existing index. The multikey documentation lists the other limits, including that a multikey index cannot cover a query on the array field itself.
Text and Geospatial Indexes
A collection can have one text index, though that index can include several fields with different weights:
db.products.insertMany([
  { name: "Trail running shoes", description: "Lightweight shoes with a grippy sole" },
  { name: "Road running shoes", description: "Cushioned shoes for long road runs" },
  { name: "Hiking boots", description: "Waterproof boots for rough trails" }
])
db.products.createIndex({ name: "text", description: "text" }, { weights: { name: 5, description: 1 }, default_language: "english" })
db.products.find({ $text: { $search: "trail" } }, { _id: 0, name: 1 })
{ "name" : "Trail running shoes" }
{ "name" : "Hiking boots" }
Stemming matched “trails” in the boots description. Text indexes are fine for simple keyword search. For relevance tuning, autocomplete or fuzzy matching, a dedicated search engine such as Elasticsearch or Solr, fed from MongoDB, does a far better job.
For locations, store GeoJSON points and use a 2dsphere index. Here is the core of a store finder:
db.stores.insertMany([
  { name: "Koregaon Park", loc: { type: "Point", coordinates: [73.8930, 18.5362] } },
  { name: "Baner", loc: { type: "Point", coordinates: [73.7868, 18.5590] } },
  { name: "Lonavala", loc: { type: "Point", coordinates: [73.4074, 18.7546] } }
])
db.stores.createIndex({ loc: "2dsphere" })
db.stores.find(
  { loc: { $near: { $geometry: { type: "Point", coordinates: [73.8567, 18.5204] }, $maxDistance: 15000 } } },
  { _id: 0, name: 1 }
)
{ "name" : "Koregaon Park" }
{ "name" : "Baner" }
Coordinates are longitude first, and $maxDistance is in metres. $near returns results sorted by distance, which is why it requires a geospatial index.
Hashed Indexes
A hashed index stores a hash of the field value. It supports equality matches but not range queries or sorts, and it cannot be unique. Its main job is hashed sharding, where it spreads monotonically increasing keys evenly across shards. I cover that in the post on sharding and shard keys. Outside sharding I rarely use one.
Wildcard Indexes
Some collections hold user-defined attributes you cannot predict, such as product specs that differ per category. Wildcard indexes, added in 4.2, index every field under a path:
db.catalog.insertMany([
  { sku: "TV-1", specs: { screenInches: 55, panel: "OLED" } },
  { sku: "FR-9", specs: { litres: 340, energyStars: 4 } }
])
db.catalog.createIndex({ "specs.$**": 1 })
db.catalog.find({ "specs.panel": "OLED" }, { _id: 0, sku: 1 })
{ "sku" : "TV-1" }
They are a tool for unpredictable fields, not a replacement for designed indexes. A wildcard index cannot be unique, TTL or compound, so you cannot pair it with a tenantId field in one index, and it serves a predicate on one field at a time. It also cannot support a sort on more than one field. The wildcard index documentation covers the remaining restrictions.
Unique, Partial, Sparse and TTL Indexes
A unique index rejects duplicates. Combined with a partial filter, it enforces uniqueness only for documents that match the filter. This is how I handle soft deletes, where a deleted account should not block a new sign-up with the same email:
db.users.createIndex(
  { email: 1 },
  { unique: true, partialFilterExpression: { deleted: false } }
)
db.users.insertOne({ email: "neha@example.com", deleted: true })
db.users.insertOne({ email: "neha@example.com", deleted: false })
db.users.countDocuments({ email: "neha@example.com" })
2
Partial indexes are also smaller, since they only hold matching documents. Sparse indexes, which skip documents missing the field, are an older and less flexible version of the same idea. So I default to partial. One catch is that the planner only uses a partial index when the query’s filter guarantees a match against the partial filter, so queries must include deleted: false.
A TTL index deletes documents a set number of seconds after the date in the indexed field. It is ideal for sessions, tokens and temporary data:
db.sessions.createIndex({ lastSeen: 1 }, { expireAfterSeconds: 1800 })
The background TTL monitor runs every 60 seconds, so documents can survive a little past their expiry. Never rely on TTL for exact timing.
MongoDB Indexing on a Live Cluster: Building Indexes Safely
In 4.2, index builds use a new optimised process that holds an exclusive lock only briefly at the start and end, and the old background option is ignored. Reads and writes continue during the build. On a replica set the primary builds the index first, and each secondary starts its own build only when it replicates the finished createIndexes entry, so a build that took an hour on the primary then runs for roughly another hour on every secondary. The index build documentation explains the details.
The build still costs CPU, disk and cache, so on large collections I run it during quieter hours, check disk space first, and create several indexes in one call so the collection is scanned once:
db.orders.createIndexes([
  { customerId: 1, createdAt: -1 },
  { "items.sku": 1, createdAt: -1 }
])
For very large collections, or clusters with no quiet hours, a rolling build is safer. Take each secondary out of the set, build the index on it as a standalone, put it back, then step down the primary and repeat on it.
Measuring Whether Your MongoDB Indexing Works
The $indexStats stage reports how many operations used each index since the last restart:
db.orders.aggregate([
  { $indexStats: {} },
  { $project: { _id: 0, name: 1, ops: "$accesses.ops" } }
])
Counters reset when a server restarts and are tracked per member. So check every member that takes reads and look at a full business cycle before acting. MongoDB 4.2 has no way to switch an index off while keeping it. That means dropping is final and a rebuild on a large collection can take a long time. Before I drop one, I save its exact definition from db.orders.getIndexes(), including options such as partialFilterExpression or collation, in the migration script. I also search the slow query log for its name in planSummary lines, because a monthly report can easily miss a two week stats window. Then I drop indexes one at a time, a few days apart, so any slowdown points straight at the cause.
My MongoDB Indexing Decision Framework
I list every important query shape (filter fields, sort, projection) and map each one to an index using ESR. Then I consolidate: if one index is a prefix of another, the longer one usually serves both. After that I pick the type by data shape. Arrays get multikey automatically, free text gets a text index or a search engine, locations get 2dsphere, unpredictable keys get wildcard, and subsets get a partial index.
Common MongoDB Indexing Mistakes
The mistake I have seen most is one index per field instead of compound indexes. MongoDB can intersect indexes in theory. In practice, though, the planner rarely picks that, and a query on three fields ends up using one index plus a lot of document reads. Next is wrong field order, usually a range field ahead of a sort field, which brings back the in-memory sort. Then too many indexes, up to the limit of 64 per collection, which slows every write. Last, indexes on low selectivity fields like a boolean on their own, which barely narrow anything unless combined with other fields.
Frequently Asked Questions
How many indexes is too many?
There is a hard limit of 64 per collection, but the real limit is write cost and memory. I start asking questions past ten or so on a write-heavy collection. Also, any index with zero uses over a full business cycle is a candidate for removal.
Does index order matter in a compound index?
Yes, a lot. Order decides which queries can use the index through the prefix rule and whether it can serve a sort. Use ESR as the default and check the result with explain.
Can an index cover a query on an array?
Not on the array field itself. A multikey index cannot cover a query that filters or projects on the array field, though it can cover queries on the non-array fields of a compound index.
Does MongoDB indexing block the database?
Not for most of the build. In 4.2, MongoDB holds an exclusive lock only briefly at the start and end of a build. So reads and writes continue while it runs. The build still adds load, so schedule big ones with care.
Run the $indexStats aggregation above on your busiest collection today and write down every index with zero ops. Save their definitions, drop them one at a time, watch your slow query log for a week after each, and recreate any that turn out to matter. Pair that with a look at your largest documents from the schema design post and you will have covered the two causes behind most slow MongoDB clusters I have seen.
Last updated on 26 October 2026
Related articles
How to Migrate from SQL to MongoDB: A Practical Playbook
A phased playbook to migrate from SQL to MongoDB: access patterns, document design, ETL, sync, validation, cutover and…
MongoDB Backup and Restore: mongodump, mongorestore, and What to Test
Back up MongoDB with mongodump, snapshots or managed backup, restore with mongorestore and oplog replay, and test restores…
MongoDB with Node.js: Mongoose vs the Native Driver
Mongoose 5 vs the MongoDB Node.js driver 3: schemas, validation, middleware, populate, lean queries, transactions, and how to…