MongoDB Sharding: When You Actually Need It and How to Choose a Shard Key
When MongoDB sharding is really needed, how clusters work, and how to choose a shard key: cardinality, frequency, hashed vs ranged, zones.

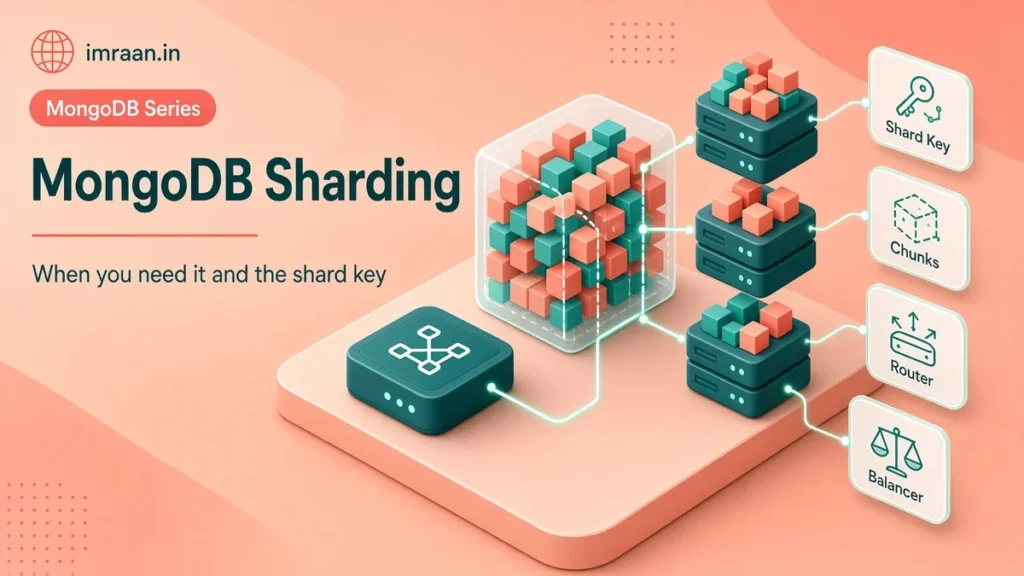
MongoDB sharding is the feature people ask me about earliest and need latest. It is how MongoDB scales writes and storage beyond one machine, and it works well. However, it also adds routers, a config server replica set, a balancer and a permanent dependency on one design decision: the shard key. Here I write about when sharding is actually justified, how a sharded cluster works and how I choose a shard key so the cluster does not have to be rebuilt a year later.
For the general theory of partitioning, hot keys and rebalancing, see my post on database sharding. If you are unsure whether you need sharding or replication, start with sharding vs replication.
Do You Need MongoDB Sharding?
Before sharding I exhaust the simpler options, because each of them is cheaper to operate:
- Fix queries and indexes. Many “we need to shard” conversations end with a missing compound index. The indexing tutorial is the first stop.
- Scale vertically. A larger instance with more RAM and faster disks is a configuration change, not an architecture change.
- Archive cold data. If most of the data is old and rarely read, move it to a cheaper collection or cluster, or export it to files.
The signals that genuinely point to sharding are a working set that no longer fits in the RAM of the largest machine you are willing to run, sustained write throughput that saturates a single primary even with good indexes, a data size per node that makes backups, restores and initial syncs take too long, and data that must physically live in particular regions. If none of those apply, a well-tuned replica set is the better system.
How MongoDB Sharding Works
A sharded cluster has three components:
- Shards, each a replica set holding a subset of the data. Everything in the replica sets post still applies to each shard.
- Config servers, a replica set storing metadata: which ranges of which collections live on which shard. Since 3.4 the config servers must run as a replica set, usually of three members.
- mongos routers, stateless processes that applications connect to. They read the metadata and send each operation to the right shards.
Data in a sharded collection is divided into ranges of shard key values called chunks. The default chunk size is 64 MB, and chunks are split automatically as inserts and updates push them past it. A background process called the balancer moves chunks between shards so each holds a similar number of chunks for that collection. It counts chunks, not bytes. With fewer than 20 chunks it migrates once two shards differ by 2 chunks, from 20 to 79 chunks the threshold is 4, and from 80 upwards it is 8. Because it counts chunks, one shard full of small chunks and a shard full of large ones can look balanced while holding very different amounts of data. The balancer documentation covers windows and throttling.
Picture it as a request flow. The application talks to a mongos, and the mongos asks the config metadata which shard owns the key in the query. Then it forwards the query to that one shard, or to all of them if it cannot tell.
Shard Key Properties
Everything about a sharded cluster depends on the shard key. I judge candidates on four properties:
- Cardinality: how many distinct values the key has. A key with few values, like
country, limits how many chunks you can ever have. Also, each chunk can only live on one shard. - Frequency: how evenly documents spread across those values. If one value holds most documents, its chunk becomes a hotspot. It may then grow into a jumbo chunk that cannot be split.
- Monotonic change: whether new values always increase, like timestamps or ObjectIds. With ranged sharding, every new insert lands at the top of the range, on one shard.
- Query isolation: whether your important queries include the key. A query with the shard key is targeted to one shard or a few. A query without it is scatter-gather: mongos sends it to every shard and merges the results.
The choosing a shard key page describes the same properties. A good key has high cardinality, even frequency, no monotonic hotspot, and appears in the queries that matter.
Ranged vs Hashed MongoDB Sharding
With ranged sharding, adjacent key values live together, so range queries on the key stay targeted. With hashed sharding, MongoDB hashes the key and distributes by hash. That spreads monotonically increasing keys evenly but turns range queries on the key into scatter-gather.
sh.enableSharding("app")

// Even write spread for an ever-increasing id; range queries on userId are broadcast.
sh.shardCollection("app.sessions", { userId: "hashed" })

// Locality per tenant, ordered by time inside each tenant.
sh.shardCollection("app.events", { tenantId: 1, createdAt: 1 })
Compound keys like { tenantId: 1, createdAt: 1 } are my usual choice for multi-tenant data. Queries for one tenant go to the shards holding that tenant, and the createdAt suffix gives enough cardinality to split a large tenant across chunks. A hashed key in 4.2 must be a single field. Try { tenantId: 1, deviceId: "hashed" } and shardCollection rejects it, saying the key can contain either a single hashed field or ranged fields. For a hashed key on an empty collection, MongoDB creates two chunks per shard up front, and the numInitialChunks option sets a higher number when you expect a heavy initial load.
The Shard Key Is Hard to Change
In MongoDB 4.2 the shard key is a one-way door. Once a collection is sharded, its key fields cannot be changed, and there is no command to unshard it. What 4.2 does allow is updating the shard key value of a single document, which earlier versions refused. It comes with conditions. The update has to go through mongos, include the full shard key in the filter, and it must run as a retryable write or inside a transaction. Without that you get this:
"errmsg" : "Must run update to shard key field in a multi-statement transaction or with retryWrites: true."
Every document must also contain every shard key field. An insert without one fails with a “does not contain shard key” error. So the application has to be ready before you shard, not after.
If you pick the wrong key, the way out is a migration. You create a new collection, shard it with the new key, copy the data across with mongodump and mongorestore or a script using bulk writes, keep it in sync while you switch the application over, then drop the old one. On a large collection that is days of work and double the disk for a while. That is why I spend far more time on the choice than on the command. The shard key documentation lists the rules.
Zones in MongoDB Sharding
Zones pin ranges of the shard key to particular shards. That is how you keep European customers’ data on European hardware or keep hot tenants on faster machines:
sh.addShardToZone("shard-eu-1", "EU")
sh.addShardToZone("shard-us-1", "US")

sh.updateZoneKeyRange("app.users", { region: "EU", userId: MinKey }, { region: "EU", userId: MaxKey }, "EU")
sh.updateZoneKeyRange("app.users", { region: "US", userId: MinKey }, { region: "US", userId: MaxKey }, "US")
The shard key must start with the field the zones use, here { region: 1, userId: 1 }. The balancer then moves ranges to satisfy the zones. The zones documentation shows tiered storage and other layouts.
Transactions and Joins Across Shards
MongoDB 4.2 is the first release where multi-document transactions work across shards. They use a two-phase commit coordinated by one shard, which adds latency and more failure modes than a single-shard transaction. I design so that most transactions touch one shard, usually by making the shard key the field the transaction groups by. $lookup is stricter. In 4.2 the collection you join to must be unsharded, so a join between two sharded collections has to happen in application code. Embedding and extended references matter even more in a sharded cluster.
Worked Example: Multi-Tenant SaaS Events
Consider an events collection for a SaaS product. Each tenant generates activity events, and dashboards query one tenant’s events over a time range.
Sharding on createdAt alone sends every insert to the shard holding the latest range, so one shard takes all writes. A hashed _id spreads writes perfectly but makes every dashboard query scatter-gather. { tenantId: 1, createdAt: 1 } targets dashboards to the shards holding a tenant and spreads tenants across shards.
The weakness of that key is a very large tenant. Its newest events all land at the top of its range, on one shard. If one tenant dominates, the next step is a key like { tenantId: 1, bucket: 1, createdAt: 1 }, where bucket is a small number from 0 to 15 that the application derives from a hash of the event id. Before changing anything I look at how data is actually spread:
sh.status()
db.getSiblingDB("app").events.getShardDistribution()
db.getSiblingDB("config").chunks.aggregate([
  { $match: { ns: "app.events" } },
  { $group: { _id: "$shard", chunks: { $sum: 1 } } }
])
db.getSiblingDB("config").chunks.find({ ns: "app.events", jumbo: true }).count()
getShardDistribution() reports data size, document counts and chunk counts per shard, the config.chunks queries show the chunk spread the balancer sees and how many chunks are flagged as jumbo, and sh.status() prints the chunk ranges themselves. A jumbo chunk usually means a single key value with too many documents. That is a key design problem, not a balancer problem.
Operating MongoDB Sharding Day to Day
Sharding changes routine operations too. I run mongos close to the application, often one per application host or a small pool behind each service. That way the extra network hop stays short. Chunk migrations copy data between shards and then delete it from the source. That costs disk I/O on both sides, so on busy clusters I set a balancer window that keeps migrations out of peak hours. Documents left behind on a shard that no longer owns their range are called orphans. The range deleter cleans them up after each migration, and queries through mongos filter them out, but direct connections to a shard will see them. After a failed migration I run cleanupOrphaned on the shard primary to remove what was left.
Backups get harder as well. A consistent backup of a sharded cluster needs every shard and the config servers captured at the same point in time. That is why I rely on managed backups from Atlas or Ops Manager, or filesystem snapshots coordinated across the cluster, rather than running mongodump against each shard. With 4.2 there is a second reason: mongodump is not a valid backup method for a sharded cluster with sharded transactions in progress. I go into the options in the backup and restore post.
Decision Framework: Picking a Shard Key
I list the top queries by frequency and importance and write down the fields each one filters on. I score each candidate key on whether those queries become targeted and whether writes spread across shards. On top of that, I check whether any single value could grow too large. Then I test with real data. I load a production-sized sample into a staging cluster, shard a copy for each candidate, and replay the main queries. Explain through mongos shows SINGLE_SHARD for a targeted query and SHARD_MERGE for one that went to several shards, and a quick count of distinct values and the largest groups per candidate catches low cardinality and hot values. The four properties from earlier are my checklist for that review.
Common MongoDB Sharding Mistakes
The mistake I have seen most is sharding on createdAt or _id with ObjectIds alone. That concentrates every insert on one shard. Close behind is sharding too early, adding operational weight to a dataset one server could handle. Low cardinality keys that cap the number of chunks, and ignoring jumbo chunks until one shard runs out of disk, round out the list.
Frequently Asked Questions
Can I unshard a collection?
Not directly. MongoDB 4.2 has no command for it. The route is to dump the collection, restore it into a new unsharded collection, switch the application over and drop the sharded one.
Should every collection be sharded?
No. Shard the few collections that are large or write-heavy and leave the rest unsharded. Unsharded collections live on the database’s primary shard, and movePrimary can move them all to another shard. However, it needs a maintenance window.
How many shards should I start with?
Enough to hold your current data and expected growth for the next year with headroom, and rarely fewer than two. Adding shards later is routine, because the balancer moves data onto new shards.
What happens to queries without the shard key?
mongos broadcasts them to every shard and merges the results. They still work, but their cost grows with the number of shards, so keep them off hot paths.
Write down your top five queries today and score three candidate shard keys against them. Score them for targeting, write spread and value frequency. Shard a staging copy of production data with the best two, replay real queries against each. Only then run sh.shardCollection in production.
Last updated on 26 October 2026
Related articles
How to Migrate from SQL to MongoDB: A Practical Playbook
A phased playbook to migrate from SQL to MongoDB: access patterns, document design, ETL, sync, validation, cutover and…
MongoDB Backup and Restore: mongodump, mongorestore, and What to Test
Back up MongoDB with mongodump, snapshots or managed backup, restore with mongorestore and oplog replay, and test restores…
MongoDB with Node.js: Mongoose vs the Native Driver
Mongoose 5 vs the MongoDB Node.js driver 3: schemas, validation, middleware, populate, lean queries, transactions, and how to…