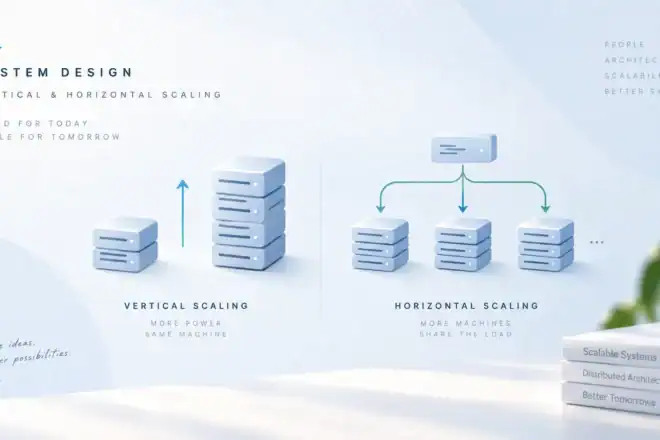
Vertical vs Horizontal Scaling: Choosing How to Grow
Scaling a system isn’t always as simple as adding more resources. As your application grows, the way you…
Category
Explore system design principles and strategies to build scalable, reliable, and high-performing software architectures for complex systems.
112 articles
Scaling a system isn’t always as simple as adding more resources. As your application grows, the way you…
What is distributed tracing: the span and trace model, context propagation across services and queues, OpenTelemetry tracing and…
Metrics monitoring for a distributed fleet: time series metrics (counters, gauges, histograms) the four golden signals, RED vs…
Structured logging, log levels, centralized logging, and log aggregation: how a distributed fleet turns scattered events into one…
Observability vs monitoring, drawn honestly: what observability is as a property, the three pillars (logs, metrics, traces) the…
TLS for Backend Engineers covers handshakes, certificates, and trust stores. Learn TLS 1.3 settings, rotation, and the failures…
Executive Summary: Splitting a monolith into services without design discipline trades one problem for distributed complexity. This post…
Blue green vs canary deployment decided: zero downtime deployment mechanics, the canary release strategy and its observation ramp,…
Retry with exponential backoff explained: backoff and jitter pacing, the retry storm math, retry budgets, what is safe…
Disaster recovery explained: RTO and RPO as the two numbers that size the plan, the disaster recovery strategies…
High availability explained: the single point of failure hunt, n+1 redundancy sizing, failover design that does not become…
Backpressure explained: the flow-control signal that travels from a slow consumer back to its producers; bounded queues where…
