Arrays in Data Structures: Traversal, Insertion, Deletion, and Complexity
How arrays store data in contiguous memory, what insert, delete and append really cost, why dynamic array appends are amortized O(1), and when to pick another structure.

A breadth-first search passes every sample test, then times out at n = 10^5. The graph logic is correct. The bug is a Python list used as a queue: every queue.pop(0) shifts all remaining elements one slot left. Thousands of those shifts turn a linear traversal into quadratic work, and the fix is a one-line change to collections.deque.
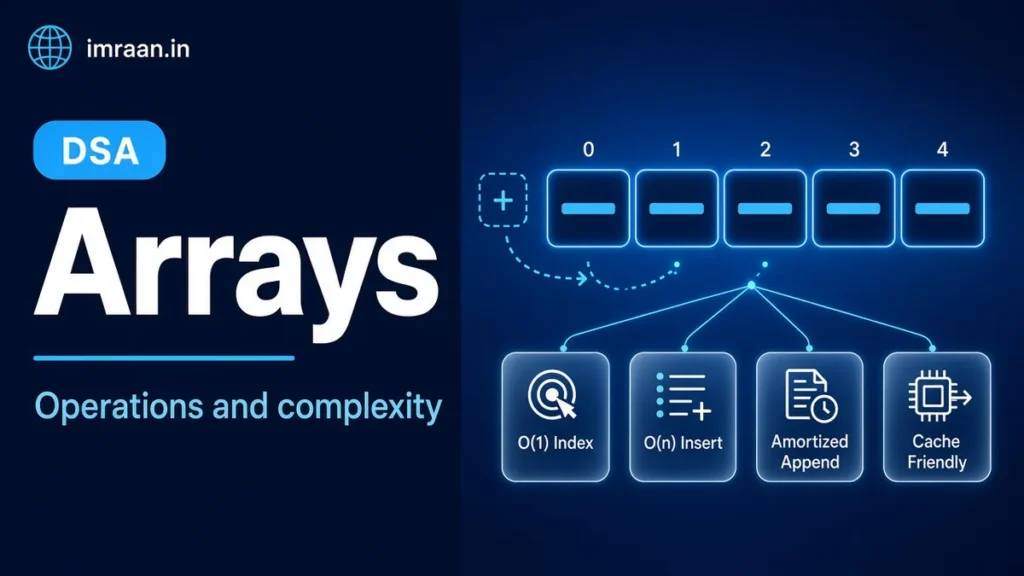
That failure is pure array mechanics. Arrays in data structures are fixed runs of equal-sized slots laid out side by side in memory and addressed by an integer index that starts at 0. Everything an array does well, and everything it does badly, follows from that one layout decision.
The code targets Python 3.12 and Java 21. You need basic loops and functions, plus Big-O notation: a way to describe how running time grows as the input size n grows. O(1) means the cost does not depend on n, and O(n) means it grows in step with n.
My position is simple. The array is the default container, and every other structure has to earn its place. Linked lists, trees, and hash tables each beat arrays at one specific operation. If you cannot name that operation for your problem, the array wins on memory, simplicity, and raw speed.
How to recognize when you need an array
Choose an array when the problem talks about positions. These signals point to it:
- Access by index. Phrases like “the element at position i”, “the kth item”, or “cell (r, c)” need constant-time indexing.
- Growth at the end only. Logs, results, and buffers that only append fit a dynamic array perfectly.
- Repeated full scans. Sums, maxima, filters, and counting passes read memory in order, which is the access pattern hardware rewards most.
- Large n with tight limits. With n up to 10^6 and a one-second limit, the low constant factor of a contiguous array often decides whether an
O(n log n)solution passes. - Fixed-size lookup tables. Counting letters with a 26-slot array, or marking visited values in a range, beats a hash map on speed and memory.
The opposite signals matter just as much. Frequent inserts at the front, membership tests on unsorted data, and sorted order under constant updates each point to a different structure.
How arrays in data structures sit in memory
An array is a base address plus a count. Because every slot has the same size, the machine finds element i with one multiply and one add. It never walks past earlier elements to get there.
 index:       0       1       2       3       4
           +-------+-------+-------+-------+-------+
 value:    |  17   |  42   |   8   |  42   |  23   |
           +-------+-------+-------+-------+-------+
 address:   1000    1004    1008    1012    1016
            ^ base

 address(i) = base + i * element_size      (4-byte ints here)
 address(3) = 1000 + 3 * 4 = 1012
That formula is the whole reason indexing is O(1) in the worst case, not just on average. The same formula explains bounds checks. In Java, every array access is checked against the length fixed at creation, and a bad index throws ArrayIndexOutOfBoundsException, as defined in the Java Language Specification chapter on arrays. Python raises IndexError, and it also accepts negative indexes that count from the end.
Python lists store references, not values
The diagram above is exact for a Java int[], where the integers themselves sit side by side. A Python list is different. According to the CPython design FAQ, a list is a contiguous array of references to objects. The references are contiguous; the objects they point to can live anywhere on the heap.
Java has the same split. An ArrayList<Integer> holds references to boxed Integer objects, while an int[] holds raw values. When memory or scan speed matters, prefer int[] in Java and the array module in Python, which stores numbers compactly with one declared type.
Traversal: visiting every element
Traversal means reading each element once, usually front to back. It costs O(n) time and O(1) extra space. In Python, prefer direct iteration, and reach for enumerate when you need the index:
scores = [17, 42, 8, 42, 23]

for value in scores:  # forward, values only
    print(value)

for i, value in enumerate(scores):  # forward, with the index
    print(i, value)

for i in range(len(scores) - 1, -1, -1):  # backward by index
    print(i, scores[i])
In Java, the enhanced for (int x : arr) loop covers the values-only case. A classic indexed loop covers everything else. Reading never causes trouble. Changing the array while you read it does, and that is the most common array bug in interviews.
A mistake I see often when candidates filter an array in place: they delete inside an index loop and then advance the index anyway. The code looks right and passes a test like [1, 2, 3]. It fails as soon as two values to delete sit next to each other.
The wrong version, in Python:
def remove_evens_wrong(nums: list[int]) -> None:
    i = 0
    while i < len(nums):
        if nums[i] % 2 == 0:
            del nums[i]  # every later element shifts left by one
        i += 1  # WRONG: skips the element that just moved into slot i
Run it on [2, 4, 5]. Deleting the 2 slides the 4 into slot 0, the index moves to 1, and the 4 is never checked. The result is [4, 5]. Even when it gets lucky, each del shifts the tail, so the loop is O(n^2) in the worst case.
The right version keeps a write pointer and truncates once:
def remove_evens(nums: list[int]) -> None:
    write = 0
    for read in range(len(nums)):
        if nums[read] % 2 != 0:  # keep odd values
            nums[write] = nums[read]
            write += 1
    del nums[write:]  # one truncation at the end, no repeated shifting
Every element is read once and written at most once, so the fix is O(n) time and O(1) extra space. This read and write pointer idea generalizes to many in-place problems. In Java, a for-each loop that removes elements throws ConcurrentModificationException, so use removeIf or an explicit Iterator.
Insertion and deletion cost depends on position
Contiguity forbids gaps. To insert at index i, every element from i to the end moves one slot right, starting from the last one so nothing is overwritten. Deletion runs the same shift leftward.
insert 99 at index 1   (size 5, capacity 8)

before:  [17][42][ 8][42][23][  ][  ][  ]
              |   |   |   |
              v   v   v   v      move 4 elements right, last one first
after:   [17][99][42][ 8][42][23][  ][  ]

work = size - index = 5 - 1 = 4 moves
Inserting at index i moves n - i elements, and deleting at i moves n - i - 1. At the end, nothing moves. At the front, everything moves. For a uniformly random position, the average is about n / 2 moves, which is still O(n).
| Operation | Best case | Average case | Worst case | Notes |
|---|---|---|---|---|
| Read or write index i | O(1) |
O(1) |
O(1) |
Address arithmetic only |
| Search, unsorted | O(1) |
O(n) |
O(n) |
Linear scan |
| Search, sorted | O(1) |
O(log n) |
O(log n) |
Binary search |
| Append at end (dynamic) | O(1) |
O(1) amortized |
O(n) on a resize |
Amortized over many appends |
| Insert at index i | O(1) at the end |
O(n) |
O(n) at the front |
Shifts n - i elements |
| Delete at end | O(1) |
O(1) amortized |
O(n) if it shrinks |
Only if the array shrinks storage |
| Delete at index i | O(1) at the end |
O(n) |
O(n) at the front |
Shifts n - i - 1 elements |
| Traverse all | O(n) |
O(n) |
O(n) |
Sequential, cache friendly |
Space is O(n) for the elements, plus unused capacity in a dynamic array. Sorted search uses the halving technique called binary search, and it only works because indexing is constant time.
Static vs dynamic arrays
A static array has a length fixed at creation. A dynamic array wraps a static one and replaces it with a bigger copy when it fills up. Both kinds of arrays in data structures share one memory layout; the difference is who manages capacity.
| Property | Static array | Dynamic array |
|---|---|---|
| Examples | Java int[], String[] |
Python list, Java ArrayList |
| Length | Fixed when created | Grows and shrinks on demand |
| Extra memory | None | Spare capacity reserved for growth |
| Append cost | Not supported; copy manually | O(1) amortized, O(n) worst |
| Best for | Known sizes, counters, grids, DP tables | Unknown sizes, collected results |
Python has no everyday static array type, since list covers both jobs. Java gives you both, and the trade-off is real: an int[] of known size skips boxing and resizing entirely.
Amortized O(1) append and the doubling argument
Amortized cost is the total cost of a sequence of operations divided by the number of operations, in the worst case. It is not an average over random inputs. A single append can still be slow; the claim is that a long run of appends is cheap overall.
Here is the doubling argument. Start with capacity 1 and double whenever the array is full. Resizes happen at sizes 1, 2, 4, and so on. Each copies the current elements. After n appends, the total copying is at most 1 + 2 + 4 + ... + n/2, which is less than n. Add the n writes themselves, and the whole sequence costs under 2n element moves.
This trace appends nine values into a doubling array that starts with capacity 1:
| Append # | Size before | Capacity before | Resize? | Copies this step | Capacity after | Total copies |
|---|---|---|---|---|---|---|
| 1 | 0 | 1 | No | 0 | 1 | 0 |
| 2 | 1 | 1 | Yes | 1 | 2 | 1 |
| 3 | 2 | 2 | Yes | 2 | 4 | 3 |
| 4 | 3 | 4 | No | 0 | 4 | 3 |
| 5 | 4 | 4 | Yes | 4 | 8 | 7 |
| 6 | 5 | 8 | No | 0 | 8 | 7 |
| 7 | 6 | 8 | No | 0 | 8 | 7 |
| 8 | 7 | 8 | No | 0 | 8 | 7 |
| 9 | 8 | 8 | Yes | 8 | 16 | 15 |
Nine appends caused 15 copies plus 9 writes, which is 24 moves and under three per append. Append number 9 alone copied 8 elements, so the worst single append is O(n). That is why the table above says amortized, and why latency-sensitive code pre-sizes its arrays.
The growth factor changes the constant, not the class
Here is the myth worth correcting: “append is O(1), full stop.” It is O(1) amortized only because capacity grows by a multiple of the current size. With any factor g greater than 1, total copying stays near n / (g - 1), which is linear. If you grow by a fixed number of slots instead, total copying becomes quadratic, and each append costs O(n) amortized.
Real runtimes pick modest factors to save memory. The CPython 3.12 list implementation in listobject.c over-allocates by about one eighth of the new size plus a small constant. Its source comment lists the growth pattern as 0, 4, 8, 16, 24, 32, 40, 52, 64, 76. In OpenJDK 21, ArrayList starts at capacity 10 on the first add and grows by half its current capacity. The official ArrayList documentation promises only amortized constant time, so treat the factor as an implementation detail.
A dynamic array from scratch
Building one yourself makes the costs concrete. This version supports get, set, append, insert, and delete by index. It counts every element copied during a resize, so the doubling argument becomes something you can measure. It also shrinks when only a quarter full. Shrinking at half full would let one append and one delete at the boundary trigger a resize every time.
In Python:
from typing import Generic, Iterator, TypeVar

T = TypeVar("T")


class DynamicArray(Generic[T]):
    """A growable array built on a fixed-size block of slots."""

    def __init__(self, step: int = 0) -> None:
        self._step = step  # 0 means double the capacity; k > 0 means add k slots
        self._capacity = step if step > 0 else 1
        self._slots: list[T | None] = [None] * self._capacity
        self._size = 0
        self.copies = 0  # element moves caused by resizing

    def __len__(self) -> int:
        return self._size

    def __iter__(self) -> Iterator[T]:
        for i in range(self._size):
            yield self._slots[i]  # type: ignore[misc]

    def _check(self, index: int) -> None:
        if not 0 <= index < self._size:
            raise IndexError(f"index {index} out of range for size {self._size}")

    def get(self, index: int) -> T:
        self._check(index)
        return self._slots[index]  # type: ignore[return-value]

    def set(self, index: int, value: T) -> None:
        self._check(index)
        self._slots[index] = value

    def _resize(self, new_capacity: int) -> None:
        new_slots: list[T | None] = [None] * new_capacity
        for i in range(self._size):
            new_slots[i] = self._slots[i]
        self.copies += self._size
        self._slots = new_slots
        self._capacity = new_capacity

    def append(self, value: T) -> None:
        self.insert(self._size, value)

    def insert(self, index: int, value: T) -> None:
        if not 0 <= index <= self._size:
            raise IndexError(f"insert index {index} out of range for size {self._size}")
        if self._size == self._capacity:
            extra = self._step if self._step > 0 else self._capacity
            self._resize(self._capacity + extra)
        for i in range(self._size, index, -1):  # shift right, last element first
            self._slots[i] = self._slots[i - 1]
        self._slots[index] = value
        self._size += 1

    def remove_at(self, index: int) -> T:
        self._check(index)
        value = self._slots[index]
        for i in range(index, self._size - 1):  # shift left
            self._slots[i] = self._slots[i + 1]
        self._size -= 1
        self._slots[self._size] = None  # drop the stale reference
        if self._step == 0 and self._capacity > 1 and self._size <= self._capacity // 4:
            self._resize(self._capacity // 2)  # shrink at 1/4 full, not 1/2
        return value  # type: ignore[return-value]


if __name__ == "__main__":
    # empty
    empty: DynamicArray[int] = DynamicArray()
    assert len(empty) == 0 and list(empty) == []
    try:
        empty.get(0)
        raise AssertionError("expected IndexError")
    except IndexError:
        pass

    # single element
    one: DynamicArray[int] = DynamicArray()
    one.append(7)
    assert one.get(0) == 7 and one.remove_at(0) == 7 and len(one) == 0

    # normal case: append, insert at front and middle, delete from middle
    arr: DynamicArray[int] = DynamicArray()
    for x in range(5):
        arr.append(x)
    arr.insert(0, -1)
    arr.insert(3, 99)
    assert list(arr) == [-1, 0, 1, 99, 2, 3, 4]
    assert arr.remove_at(3) == 99
    arr.set(0, 10)
    assert list(arr) == [10, 0, 1, 2, 3, 4]

    # duplicates: removing one 42 leaves the other
    dup: DynamicArray[int] = DynamicArray()
    for x in (42, 5, 42):
        dup.append(x)
    dup.remove_at(0)
    assert list(dup) == [5, 42]

    # edge case: inserting at index == size is legal, size + 1 is not
    arr.insert(len(arr), 50)
    assert arr.get(len(arr) - 1) == 50
    try:
        arr.insert(len(arr) + 1, 60)
        raise AssertionError("expected IndexError")
    except IndexError:
        pass

    # the doubling argument, measured: copies stay below n
    doubling: DynamicArray[int] = DynamicArray()
    additive: DynamicArray[int] = DynamicArray(step=16)
    for x in range(1024):
        doubling.append(x)
        additive.append(x)
    assert doubling.copies == 1023  # 1 + 2 + 4 + ... + 512
    assert additive.copies == 32256  # 16 * (1 + 2 + ... + 63)
    print("doubling copies:", doubling.copies, "additive copies:", additive.copies)
    print("all tests passed")
The same structure in Java, storing elements in an Object[] the way ArrayList does:
import java.util.ArrayList;
import java.util.List;

public class DynamicArrayDemo {

    static class DynamicArray<T> {
        private final int step; // 0 means double the capacity; k > 0 means add k slots
        private Object[] slots;
        private int size;
        long copies; // element moves caused by resizing

        DynamicArray() {
            this(0);
        }

        DynamicArray(int step) {
            this.step = step;
            this.slots = new Object[step > 0 ? step : 1];
        }

        int size() {
            return size;
        }

        private void check(int index) {
            if (index < 0 || index >= size) {
                throw new IndexOutOfBoundsException("index " + index + " for size " + size);
            }
        }

        @SuppressWarnings("unchecked")
        T get(int index) {
            check(index);
            return (T) slots[index];
        }

        void set(int index, T value) {
            check(index);
            slots[index] = value;
        }

        private void resize(int newCapacity) {
            Object[] next = new Object[newCapacity];
            for (int i = 0; i < size; i++) {
                next[i] = slots[i];
            }
            copies += size;
            slots = next;
        }

        void append(T value) {
            insert(size, value);
        }

        void insert(int index, T value) {
            if (index < 0 || index > size) {
                throw new IndexOutOfBoundsException("insert index " + index + " for size " + size);
            }
            if (size == slots.length) {
                int extra = step > 0 ? step : slots.length;
                resize(slots.length + extra);
            }
            for (int i = size; i > index; i--) { // shift right, last element first
                slots[i] = slots[i - 1];
            }
            slots[index] = value;
            size++;
        }

        T removeAt(int index) {
            T value = get(index);
            for (int i = index; i < size - 1; i++) { // shift left
                slots[i] = slots[i + 1];
            }
            size--;
            slots[size] = null; // drop the stale reference
            if (step == 0 && slots.length > 1 && size <= slots.length / 4) {
                resize(slots.length / 2); // shrink at 1/4 full, not 1/2
            }
            return value;
        }

        List<T> toList() {
            List<T> out = new ArrayList<>();
            for (int i = 0; i < size; i++) {
                out.add(get(i));
            }
            return out;
        }
    }

    static void check(boolean condition, String message) {
        if (!condition) {
            throw new AssertionError(message);
        }
    }

    public static void main(String[] args) {
        // empty
        DynamicArray<Integer> empty = new DynamicArray<>();
        check(empty.size() == 0 && empty.toList().isEmpty(), "empty");
        try {
            empty.get(0);
            throw new AssertionError("expected IndexOutOfBoundsException");
        } catch (IndexOutOfBoundsException expected) {
            // ok
        }

        // single element
        DynamicArray<Integer> one = new DynamicArray<>();
        one.append(7);
        check(one.get(0) == 7 && one.removeAt(0) == 7 && one.size() == 0, "single");

        // normal case
        DynamicArray<Integer> arr = new DynamicArray<>();
        for (int x = 0; x < 5; x++) {
            arr.append(x);
        }
        arr.insert(0, -1);
        arr.insert(3, 99);
        check(arr.toList().equals(List.of(-1, 0, 1, 99, 2, 3, 4)), "insert");
        check(arr.removeAt(3) == 99, "removeAt");
        arr.set(0, 10);
        check(arr.toList().equals(List.of(10, 0, 1, 2, 3, 4)), "set");

        // duplicates
        DynamicArray<Integer> dup = new DynamicArray<>();
        for (int x : new int[] {42, 5, 42}) {
            dup.append(x);
        }
        dup.removeAt(0);
        check(dup.toList().equals(List.of(5, 42)), "duplicates");

        // edge case: insert at index == size is legal, size + 1 is not
        arr.insert(arr.size(), 50);
        check(arr.get(arr.size() - 1) == 50, "insert at end");
        try {
            arr.insert(arr.size() + 1, 60);
            throw new AssertionError("expected IndexOutOfBoundsException");
        } catch (IndexOutOfBoundsException expected) {
            // ok
        }

        // the doubling argument, measured
        DynamicArray<Integer> doubling = new DynamicArray<>();
        DynamicArray<Integer> additive = new DynamicArray<>(16);
        for (int x = 0; x < 1024; x++) {
            doubling.append(x);
            additive.append(x);
        }
        check(doubling.copies == 1023, "doubling copies");
        check(additive.copies == 32256, "additive copies");
        System.out.println("PASS");
    }
}
The final test is the original insight of this section in runnable form. For 1,024 appends, doubling copies 1,023 elements in total. Growing by 16 slots at a time copies 32,256 elements, about 31 times more, and that gap widens linearly as n grows. Space is O(n) in both versions, because the quarter-full shrink rule keeps capacity within a constant factor of the live size.
Built-in arrays in Python and Java and their gotchas
You will rarely ship your own dynamic array, but you will hit the quirks of the built-ins every week. These programs show the ones that cause real bugs. In Python:
import sys

if __name__ == "__main__":
    # 1. Multiplying a nested list copies references, not rows
    grid = [[0] * 3] * 3
    grid[0][0] = 1
    assert grid == [[1, 0, 0], [1, 0, 0], [1, 0, 0]]  # every row changed
    grid = [[0] * 3 for _ in range(3)]
    grid[0][0] = 1
    assert grid == [[1, 0, 0], [0, 0, 0], [0, 0, 0]]

    # 2. insert past the end does not raise; it appends
    nums = [1, 2, 3]
    nums.insert(100, 4)
    assert nums == [1, 2, 3, 4]

    # 3. Negative indexes count from the end; slices copy
    assert nums[-1] == 4
    part = nums[1:3]
    part[0] = 99
    assert nums == [1, 2, 3, 4]  # the slice was a copy

    # 4. Watch capacity grow: length -> allocated slots (CPython 3.12, 64-bit)
    a: list[int] = []
    header = sys.getsizeof(a)
    last = header
    growth: list[tuple[int, int]] = []
    for i in range(40):
        a.append(i)
        size = sys.getsizeof(a)
        if size != last:
            growth.append((len(a), (size - header) // 8))
            last = size
    print(growth)  # length at which a resize happened, new capacity
    assert len(growth) < 40  # far fewer resizes than appends
The last block prints the length at which each resize happened and the new capacity in slots. On a 64-bit CPython 3.12 build, it shows capacities of 4, 8, 16, 24, 32, and 40, matching the source comment. The same checks in Java:
import java.util.ArrayList;
import java.util.Arrays;
import java.util.ConcurrentModificationException;
import java.util.List;

public class ArrayGotchas {
    static void check(boolean condition, String message) {
        if (!condition) {
            throw new AssertionError(message);
        }
    }

    public static void main(String[] args) {
        // 1. Primitive arrays have a fixed length and default values
        int[] counts = new int[4];
        check(counts.length == 4 && counts[3] == 0, "defaults to zero");
        try {
            counts[4] = 1;
            throw new AssertionError("expected ArrayIndexOutOfBoundsException");
        } catch (ArrayIndexOutOfBoundsException expected) {
            // every access is bounds-checked
        }

        // 2. Arrays.asList is a fixed-size view: set works, add does not
        List<Integer> view = Arrays.asList(3, 1, 2);
        view.set(0, 9);
        try {
            view.add(4);
            throw new AssertionError("expected UnsupportedOperationException");
        } catch (UnsupportedOperationException expected) {
            // copy into an ArrayList if you need to grow it
        }

        // 3. remove(int) removes by index, remove(Object) removes by value
        List<Integer> nums = new ArrayList<>(List.of(10, 20, 30));
        nums.remove(1);                   // removes index 1 (the value 20)
        check(nums.equals(List.of(10, 30)), "remove by index");
        nums.remove(Integer.valueOf(10)); // removes the value 10
        check(nums.equals(List.of(30)), "remove by value");

        // 4. Removing inside a for-each loop fails fast
        List<Integer> data = new ArrayList<>(List.of(1, 2, 3, 4));
        try {
            for (int x : data) {
                if (x == 1) {
                    data.remove(Integer.valueOf(x));
                }
            }
            throw new AssertionError("expected ConcurrentModificationException");
        } catch (ConcurrentModificationException expected) {
            // use removeIf or an explicit Iterator instead
        }
        List<Integer> safe = new ArrayList<>(List.of(1, 2, 3, 4));
        safe.removeIf(x -> x % 2 == 0);
        check(safe.equals(List.of(1, 3)), "removeIf");
        System.out.println("PASS");
    }
}
Two of these deserve emphasis. Arrays.asList returns a fixed-size view, so add throws UnsupportedOperationException. And list.remove(1) on a List<Integer> removes index 1, not the value 1, because the int overload wins.
Measure front inserts yourself
Never trust a benchmark number you cannot rerun. This script times three ways to build a sequence of n items. Your numbers will vary by machine, but the shape will not:
import timeit
from collections import deque


def fill_back(n: int) -> list[int]:
    out: list[int] = []
    for i in range(n):
        out.append(i)
    return out


def fill_front(n: int) -> list[int]:
    out: list[int] = []
    for i in range(n):
        out.insert(0, i)  # shifts every existing element
    return out


def fill_deque_front(n: int) -> deque[int]:
    out: deque[int] = deque()
    for i in range(n):
        out.appendleft(i)
    return out


if __name__ == "__main__":
    assert fill_front(5) == [4, 3, 2, 1, 0]
    assert list(fill_deque_front(5)) == fill_front(5)
    for n in (5_000, 10_000, 20_000):
        back = timeit.timeit(lambda: fill_back(n), number=3)
        front = timeit.timeit(lambda: fill_front(n), number=3)
        dq = timeit.timeit(lambda: fill_deque_front(n), number=3)
        print(f"n={n:>6}  append={back:.4f}s  insert(0)={front:.4f}s  deque.appendleft={dq:.4f}s")
Watch how the insert(0) column grows as n doubles, compared with the other two. That growth is the shifting cost from the insertion diagram, and it is the same cost behind the pop(0) queue bug. A deque or a circular buffer avoids that cost.
Cache locality: why arrays beat linked lists in practice
A CPU does not fetch single bytes from main memory. It loads a whole cache line, often 64 bytes, and hardware prefetchers predict sequential access. When you scan an array, the next elements are usually already in cache. A linked list scatters nodes across the heap, so each step can be a fresh cache miss.
This is why the textbook advantage of linked lists often disappears. Inserting into the middle of a list is O(1) only once you hold the node. Finding that node is an O(n) walk of pointer chasing, while an array finds the slot instantly and shifts the tail with one block memory move.
One caveat applies to Python. A list’s references are contiguous, but the integer objects they point to are not. You still get locality on the reference array, just less than a Java int[] provides.
Where this shows up in real systems
- CPython’s list type. Every Python list is a dynamic array of object references with mild over-allocation, as the listobject.c source shows. That is why
appendis cheap andinsert(0, x)is not. - Java’s ArrayList. It wraps an
Object[]that OpenJDK replaces with a larger copy when full. The official documentation notes that callingensureCapacitybefore a bulk load may reduce incremental reallocation. - JVM bounds checking. The Java Language Specification requires a range check on every array access. That check turns what would be silent memory corruption in C into a clean exception you can catch and debug.
How to explain it in an interview
Interviewers rarely ask “what is an array.” They probe whether you know what your array operations cost. Talk through it in this order.
- State the layout. Contiguous memory, equal-sized slots, address computed from the index.
- Name the strength. Constant-time indexing in the worst case and cache-friendly scans.
- Name the bottleneck. Middle inserts and deletes shift
n - ielements. - Explain dynamic growth. Geometric resizing makes append amortized
O(1); one append can still beO(n). - Cover edge cases. Empty array, single element, index equal to size, and duplicates.
Expect three follow-ups. Why double instead of adding 100 slots? What happens to memory after many deletes? Is list.pop(0) fine for a queue? A weak answer says append is O(1). A strong answer says amortized, explains the geometric series, and mentions the latency spike on the resizing append.
A decision framework for picking a sequence structure
- Do you need access by position? If yes, start with an array. Nothing else gives worst-case
O(1)indexing. - Do you only add and remove at the end? A dynamic array is ideal, and it doubles as a stack.
- Do you add or remove at both ends? Use
collections.dequeorArrayDeque, bothO(1)at each end. - Do you mostly ask “is x present?” Use a hash set for average
O(1)membership checks. - Do you need sorted order under frequent inserts? Use a balanced tree such as Java’s
TreeMap, or a sorted array if inserts are rare. - Is the size known and the data numeric? Use
int[]in Java or thearraymodule in Python to save memory.
When not to use an array
- Queues that pop from the front. Each
pop(0)orremove(0)isO(n). Use a deque or a circular buffer instead. - Membership tests on large unsorted data. Each
x in listis a linear scan, so a loop of them is quadratic. Use asetorHashSet. - Sorted data with interleaved inserts and queries. Each insert into a sorted array is
O(n). A balanced binary search tree does both inO(log n).
Common mistakes
- Calling append
O(1)without “amortized.” It hides theO(n)resize. An interviewer tests this with “what is the worst case for one append?” - Deleting inside a forward index loop. It skips the element that shifts into the current slot. The input
[2, 4, 5]with “remove evens” exposes it. - Using
list.pop(0)as a queue. It passes small tests and times out near n = 10^5. Profiling a BFS on a long path graph exposes it. - Building a grid with
[[0] * m] * n. Every row is the same list object, so one write changes all rows. Any write togrid[0][0]exposes it. - Off-by-one at the boundary. Inserting at index
sizeis legal; reading indexsizeis not. Test with an empty array and with index equal to length. - Calling
remove(1)on aList<Integer>to remove the value 1. Java picks the index overload. Useremove(Integer.valueOf(1)).
Practice problems
| Problem | Difficulty | The twist |
|---|---|---|
| Running Sum of 1d Array | Easy | Overwrite each slot with the total so far, in place |
| Remove Element | Easy | Compact kept values with a write index instead of deleting |
| Merge Sorted Array | Easy | Fill from the back so no element shifts twice |
| Find All Numbers Disappeared in an Array | Easy | Use the sign of each slot as a visited flag |
| Spiral Matrix | Medium | Traverse a 2D array with four shrinking boundaries |
| Product of Array Except Self | Medium | Two passes over the array, no division |
| Set Matrix Zeroes | Medium | Reuse the first row and column as marker storage |
| First Missing Positive | Hard | Place each value at its own index to get O(1) extra space |
Once these feel easy, move on to common array patterns such as Kadane’s algorithm and the Dutch National Flag partition. More DSA topics are on the DSA hub.
Key takeaways
- Index reads and writes are
O(1)in the worst case because the address is computed, not searched. - Insert and delete at index
ishiftn - ielements, so only the end is cheap. - Say “amortized
O(1)” for appends, and know that one append can costO(n). - Geometric growth keeps total copying linear; fixed-size growth makes it quadratic.
- Filter in place with a write pointer, never by deleting inside a forward loop.
- Prefer primitive arrays (
int[], thearraymodule) when memory and scan speed matter. - Switch away from arrays only for a named reason: front removal, membership tests, or sorted inserts.
Frequently Asked Questions
Why is accessing an array element O(1)?
Every slot has the same size and the slots sit next to each other in memory. The address of element i is the base address plus i times the slot size, which takes the same time for any i. No other elements are visited on the way.
Is Python list append really O(1)?
It is O(1) amortized, not O(1) for every call. CPython over-allocates spare slots, so most appends just write into free space, but an append that finds the list full copies every reference into a larger block. Over many appends the copying averages out to a constant per append.
What is the difference between an array and an ArrayList in Java?
A Java array has a length fixed at creation and can hold primitives such as int directly. An ArrayList grows automatically by copying into a larger backing array, but it only holds object references, so integers are boxed. Use an array for known sizes and numeric data, and an ArrayList when the size is unknown.
When should I use a linked list instead of an array?
Use a linked list when you already hold references to nodes and must insert or remove at those nodes often, as in an LRU cache. For most other workloads an array is faster in practice because sequential memory access is cache friendly. Finding a position in a linked list is a linear walk, which cancels its cheap insert.
Default to the array until an operation proves it wrong
Arrays in data structures give you constant-time indexing and the fastest possible scans, and they charge you for every shift. Count the shifts your workload causes. If they stay at the end, keep the array. If they land at the front or the middle, choose the structure built for that operation.
Rule of thumb: if you cannot name the operation an array makes slow, you should be using an array.
Originally posted on 22 November 2026 and post last modified on 22 November 2026
Related articles
Common Array Patterns for Coding Interviews: Kadane’s, Dutch National Flag, and Rotation
Three in-place array patterns for coding interviews: Kadane's algorithm, the Dutch National Flag partition and rotation by reversal,…
String Manipulation Techniques: Reversal, Palindromes, and Anagrams
String manipulation in Python and Java: why immutability makes naive concatenation O(n^2), safe ways to reverse, and how…