How to Connect Node.js to PostgreSQL: pg, Pooling, and CRUD
Connect Node.js to PostgreSQL with pg 7: one PostgreSQL pool, parameterized CRUD, a transaction helper and constraint errors mapped to HTTP codes.


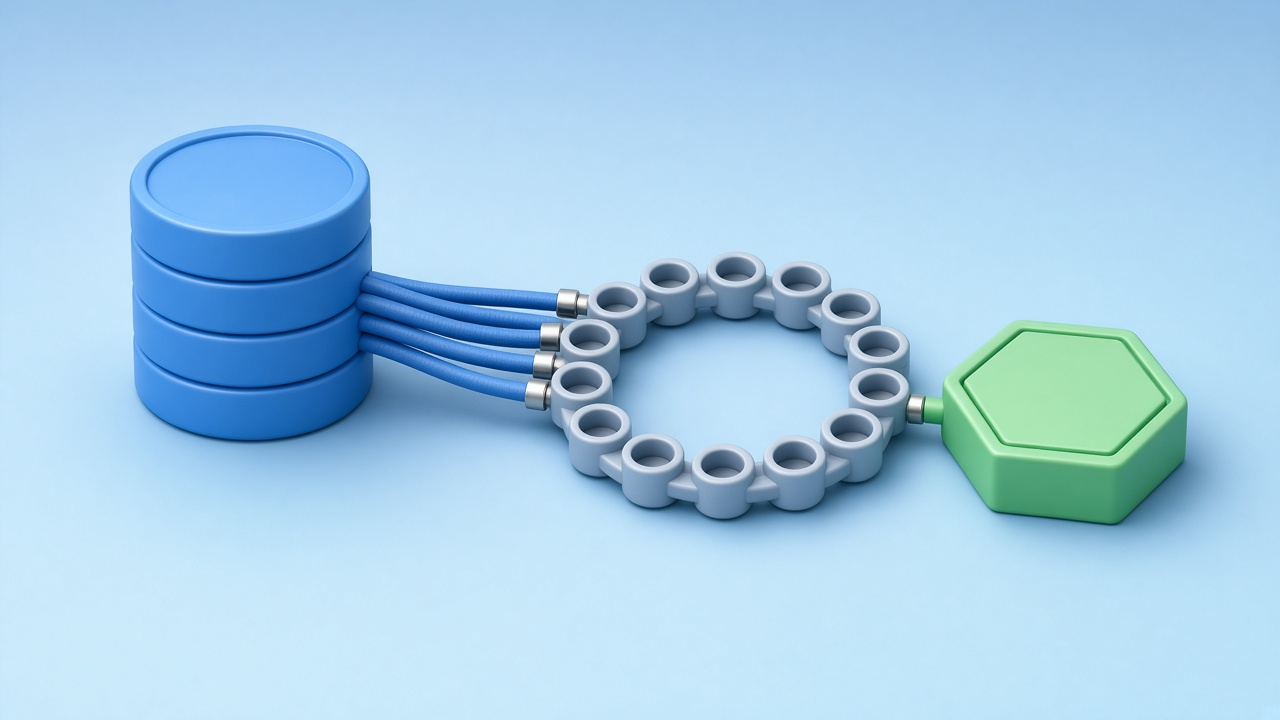
Many Express examples keep their data in a JavaScript Map. That is fine for learning, but every restart wipes it. Here I write about how I connect Node.js to PostgreSQL with the pg package: a PostgreSQL pool configured with real limits, parameterized CRUD queries, transactions and a repository that drops into an existing service layer.
The code runs on Node 10 LTS, node-postgres (the pg package) version 7 and PostgreSQL 11. The DATABASE_URL comes from a config module that validates environment variables at startup. If you are still choosing a database, my comparison of SQL vs NoSQL under real constraints explains why I default to PostgreSQL for data like this.
The schema
I keep the table small and let the database enforce the rules it is good at:
CREATE EXTENSION IF NOT EXISTS pgcrypto;

CREATE TABLE tasks (
  id          uuid PRIMARY KEY DEFAULT gen_random_uuid(),
  title       text NOT NULL CHECK (char_length(title) BETWEEN 3 AND 200),
  done        boolean NOT NULL DEFAULT false,
  created_at  timestamptz NOT NULL DEFAULT now(),
  CONSTRAINT tasks_title_unique UNIQUE (title)
);

CREATE INDEX tasks_done_created_idx ON tasks (done, created_at);
In PostgreSQL 11, gen_random_uuid() comes from the pgcrypto extension, so the first line enables it. The CHECK mirrors the Joi rule in the API. That duplication is deliberate, because a script or a second service could write to this table without going through the API. Also, the unique constraint gives the API a real reason to return 409 Conflict.
Why a PostgreSQL pool, and how to configure it
Opening a PostgreSQL connection is expensive. It needs a TCP handshake, authentication and a new server process on the database side. Doing that for every HTTP request adds latency and can exhaust the server’s connection limit under load. Instead, a PostgreSQL pool keeps a few connections open and lends them out.
npm install pg@7// src/db/pool.js
const { Pool } = require('pg');
const config = require('../config');
const pool = new Pool({
connectionString: config.databaseUrl,
max: 10, // connections per Node process
idleTimeoutMillis: 30000, // close idle connections after 30s
connectionTimeoutMillis: 2000, // fail fast when the pool is exhausted
});
// Every new connection gets a statement timeout.
pool.on('connect', (client) => {
client.query('SET statement_timeout TO 5000');
});
// An idle client can fail too, for example when the database restarts.
pool.on('error', (err) => {
console.error('idle PostgreSQL client error', err.message);
});
module.exports = { pool };Every option on this PostgreSQL pool prevents a specific outage.
First, max. The default is 10, and I write it down anyway. Remember that the PostgreSQL pool limit applies per process. Four Node processes behind a cluster, each with max: 10, can open 40 connections. So size the pool against the database’s max_connections, not against your hopes.
Second, connectionTimeoutMillis. Without it, a request waits forever when all connections are busy. With it, the request fails after two seconds with a clear error. A central error handler can then answer with a 503 instead of letting the request hang.
Third, the statement timeout. A single slow query can hold a connection for minutes, and a few of those starve the pool. The statement_timeout setting makes PostgreSQL cancel any statement that runs longer than five seconds. Because pg queues queries per client, the SET always runs before the first real query.
Finally, the error listener. If the database restarts, idle clients emit an error. Without a listener, that error crashes the process. The PostgreSQL pool removes the broken client on its own, so logging is enough.
For every option, see the node-postgres pool documentation.
CRUD with parameterized queries
The repository replaces an in-memory Map inside the service. It has the same method names and returns plain objects, so the routes and controllers do not change.
// src/repositories/tasks.repository.js
const UPDATABLE = ['title', 'done'];

function toTask(row) {
  return { id: row.id, title: row.title, done: row.done, createdAt: row.created_at };
}

function createTasksRepository(pool) {
  return {
    async list({ done, limit, offset }) {
      const params = [];
      let where = '';
      if (done !== undefined) {
        params.push(done);
        where = 'WHERE done = $1';
      }
      params.push(limit, offset);
      const n = params.length;

      const { rows } = await pool.query(
        `SELECT id, title, done, created_at, count(*) OVER ()::int AS total
           FROM tasks ${where}
          ORDER BY created_at DESC
          LIMIT $${n - 1} OFFSET $${n}`,
        params
      );
      return { items: rows.map(toTask), total: rows.length ? rows[0].total : 0 };
    },

    async get(id) {
      const { rows } = await pool.query(
        'SELECT id, title, done, created_at FROM tasks WHERE id = $1',
        [id]
      );
      return rows.length ? toTask(rows[0]) : null;
    },

    async create({ title }) {
      const { rows } = await pool.query(
        'INSERT INTO tasks (title) VALUES ($1) RETURNING id, title, done, created_at',
        [title]
      );
      return toTask(rows[0]);
    },

    async update(id, changes) {
      const fields = Object.keys(changes).filter((key) => UPDATABLE.includes(key));
      const sets = fields.map((key, i) => `${key} = $${i + 2}`).join(', ');
      const { rows } = await pool.query(
        `UPDATE tasks SET ${sets} WHERE id = $1 RETURNING id, title, done, created_at`,
        [id].concat(fields.map((key) => changes[key]))
      );
      return rows.length ? toTask(rows[0]) : null;
    },

    async remove(id) {
      const { rowCount } = await pool.query('DELETE FROM tasks WHERE id = $1', [id]);
      return rowCount === 1;
    },
  };
}

module.exports = { createTasksRepository };
Every value travels as a parameter ($1, $2), never as part of the SQL string. PostgreSQL receives the query text and the values separately, so a title such as '); DROP TABLE tasks; -- is stored as harmless text. The node-postgres query guide explains the mechanics, and my guide to SQL injection prevention covers the other layers of defense.
The update method is the one place that builds SQL dynamically, so it deserves care. Column names cannot be parameters. That is why the code filters them against the UPDATABLE allow-list first. Values still go through placeholders.
Two type details also matter. PostgreSQL’s count(*) returns a bigint, and pg returns bigint as a string to avoid losing precision. Hence the ::int cast. Timestamps, on the other hand, come back as JavaScript Date objects, and res.json serialises them as ISO strings.
Finally, I translate database errors into domain errors in the service, not in the controller:
async create(input) {
  try {
    return await repository.create(input);
  } catch (err) {
    if (err.code === '23505') {
      throw new AppError(409, 'Conflict', 'A task with this title already exists');
    }
    throw err;
  }
}
The code 23505 is PostgreSQL’s unique violation. Any other error stays a 500. Here AppError is a small Error subclass that carries an HTTP status for the error handler.
Transactions: one client from the PostgreSQL pool, always released
A transaction must run on a single connection. If you call pool.query three times, each call may use a different connection, and your BEGIN protects nothing. So you check out a client and run every statement on it:
async function withTransaction(pool, work) {
  const client = await pool.connect();
  try {
    await client.query('BEGIN');
    const result = await work(client);
    await client.query('COMMIT');
    return result;
  } catch (err) {
    await client.query('ROLLBACK');
    throw err;
  } finally {
    client.release();
  }
}

// Usage: archive finished tasks atomically.
await withTransaction(pool, async (client) => {
  await client.query('INSERT INTO tasks_archive SELECT * FROM tasks WHERE done');
  await client.query('DELETE FROM tasks WHERE done');
});
The finally block is the important part. A client that is never released leaks from the PostgreSQL pool. After ten leaks, every request waits for connectionTimeoutMillis and then fails. The helper makes that mistake impossible, because no caller ever touches release. You can see the same pattern on the node-postgres transactions page.
Wiring the PostgreSQL pool into the app
// src/server.js
const config = require('./config');
const { pool } = require('./db/pool');
const { createTasksRepository } = require('./repositories/tasks.repository');
const { createTasksService } = require('./services/tasks.service');
const { createApp } = require('./app');

async function start() {
  await pool.query('SELECT 1'); // fail at startup, not on the first request
  const tasksService = createTasksService(createTasksRepository(pool));
  createApp({ tasksService }).listen(config.port);
}

start().catch((err) => {
  console.error('startup failed:', err.message);
  process.exit(1);
});
The SELECT 1 check makes a wrong password or a missing database fail at deploy time. Also, the service methods are now async. Express 4 does not catch rejected promises, so the controllers use a small asyncHandler wrapper that passes them to next. I explain that trap in Node.js error handling middleware. Apart from that, the routes and controllers stay exactly as they were.
On shutdown, call pool.end() after the HTTP server has stopped. Requests in flight still need their connections, so the pool closes last.
Testing against the real database
I test repositories against a real PostgreSQL instance, usually in Docker, and not against mocks. Mocks happily accept SQL with a syntax error. A real database does not. Each test run creates the schema in a fresh test database, and each test truncates the tables it uses. I also run that suite with --runInBand, so test files do not fight over the same tables.
Troubleshooting the PostgreSQL pool
| Symptom | Cause | Fix |
|---|---|---|
| Requests hang, then fail after 2 seconds | The pool is exhausted, often by leaked clients | Release every client in finally; check for slow queries |
| Process crashes when the database restarts | No error listener on the pool |
Add pool.on('error', ...) |
sorry, too many clients already |
Pool size times process count exceeds max_connections |
Lower max or add PgBouncer |
| Counts arrive as strings | bigint is returned as a string |
Cast with ::int or parse in code |
function gen_random_uuid() does not exist |
pgcrypto is not enabled | Run CREATE EXTENSION pgcrypto |
Plain pg or something bigger?
I start with plain pg and a repository layer. It keeps the SQL visible, and PostgreSQL features such as window functions and ON CONFLICT stay one line away. A query builder such as Knex helps when queries are assembled from many optional filters. An ORM such as Sequelize or TypeORM pays off when a team wants models and migrations in one tool, at the cost of less control over the SQL.
If your data is document-shaped, the same repository idea works with MongoDB and its official Node.js driver.
Common PostgreSQL pool mistakes
- Building SQL with string concatenation. It invites SQL injection. Use placeholders for every value.
- Creating a new Pool per request. That defeats the purpose and exhausts connections. Create one PostgreSQL pool per process.
- Running a transaction through
pool.query. Each call may use a different connection. - Forgetting
client.release(). The pool leaks until the app stops answering. - No statement timeout. One runaway query blocks a connection for minutes.
FAQ
How do I connect Node.js to PostgreSQL?
Install the pg package, create one Pool with your connection string, and run queries with pool.query and parameter placeholders. Create the pool once at startup and share it across the app.
What size should a PostgreSQL pool be?
Start with the default of 10 per process and measure. Multiply the pool size by the number of Node processes and keep the total well below the database’s max_connections setting.
How do I run a transaction with node-postgres?
Check out a client with pool.connect, run BEGIN, your statements and COMMIT on that same client, roll back on error, and always release the client in a finally block.
Does pg protect against SQL injection?
Yes, when you pass values as parameters such as $1 instead of putting them in the SQL string. Column and table names cannot be parameters, so check those against an allow-list.
Make the database fail loudly and early: check the connection at startup, cap the pool, and time out slow statements. Keep every value in a placeholder and every transaction on one client, and the PostgreSQL pool stays healthy under load.
Last updated on 31 October 2026
Related articles
Nodemon not refreshing page automatically
while setting up a MERN app, i was using nodemon to reflect code edits and render the new…
Graceful Shutdown and Process Signals in Node.js
Graceful shutdown for Node.js and Express: SIGTERM handling, keep-alive sockets, closing the pool last, readiness checks and Docker…
Node.js Performance: Clustering, Worker Threads, and What Actually Helps
Real benchmarks of the cluster module and worker threads on Node 10, plus event loop lag checks, PM2…